


Securing a data engineer role can be a game-changer in your career, offering opportunities to work with cutting-edge technologies, solve complex problems, and significantly impact business decisions. However, the path to landing this converted position is often challenging, with interviews designed to test your technical expertise, problem-solving abilities, and understanding of data engineering concepts.
This guide will walk you through everything you need to know to ace your data engineer interview. Whether you’re brushing up on your SQL skills, mastering data modeling, or preparing for questions about big data technologies, this article provides practical tips and real-world examples to approach each aspect of the interview with confidence. By the end, you’ll be equipped with actionable insights to give you the edge you need to succeed.
Understand the Data Engineer Role
Before diving into the technical nitty-gritty, it’s crucial to have a solid understanding of what the role of a data engineer entails. This foundational knowledge will not only help you during your interview but also ensure that you align your skills and experience with the expectations of the job.
Key Responsibilities
As described in bigtechinterviews.com/meta-data-engineer-interview-a-complete-guide/, a data engineer’s role revolves around designing, constructing, and managing scalable data systems.
You’ll be responsible for:
- Data Ingestion: Developing systems to ingest data from various sources, ensuring it’s accurate, timely, and accessible.
- Data Processing: Transforming raw data into a usable format through cleaning, enriching, and aggregating processes.
- ETL/ELT Pipelines: Building and maintaining Extract, Transform, Load (ETL) or Extract, Load, Transform (ELT) pipelines that move data from one system to another.
- Data Modeling: Creating data models that define the structure, storage, and retrieval of data, optimizing for both performance and accessibility.
- Collaboration: Working closely with data scientists, analysts, and other stakeholders to ensure data systems meet business requirements.
Why it Matters
Understanding these responsibilities is vital to tailoring your interview responses. Demonstrating your knowledge of the full scope of the role will help you present yourself as a well-rounded candidate capable of effectively handling the job’s demands. Aligning your skills and experiences with these key areas will set you apart in the interview process.
Preparation Tip
To prepare effectively, start by reviewing the job description thoroughly. Identify the responsibilities and skills the employer seeks and consider how your past experiences align with these expectations. Familiarize yourself with common data engineer interview questions focusing on role-specific tasks. You can find a comprehensive list of such questions here.
By grounding yourself in the role’s core responsibilities, you’ll be better prepared to answer questions confidently and demonstrate your suitability for the position.
Master the Core Technical Skills
To excel as a data engineer, technical expertise is indispensable. Your interview will rigorously test your ability to manage large datasets, design efficient data pipelines, and optimize data systems. Mastering these technical skills will not only prepare you to tackle complex problems but also demonstrate your readiness to thrive in a data engineering role.
Let’s dive into the essential areas where your proficiency will be evaluated.
SQL Proficiency
Proficiency in SQL is a cornerstone of data engineering. Your SQL skills (as described in the SQL Cheat Sheet) will be thoroughly evaluated during interviews, from writing complex queries to managing and manipulating data to optimizing these queries for performance. Below are some key areas to focus on:
Complex Joins: Understanding and Applying Different Join Types
Mastering the different join types is imperative for effectively combining data from multiple tables. Joins allow you to retrieve and analyze related data stored in disparate tables, enabling you to derive meaningful insights from this data.
Let’s dive into the key types of joins and how they can be applied in a real-world scenario.
What is a Join?
In summary, a join is an SQL operation that combines rows from two or more tables based on a related column (or related columns). The result is a new dataset that merges information from the original tables into a single dataset, allowing you to work with a more comprehensive set of data. Refer to SQL Joins: A Complete Guide for 2024 for more information on SQL joins.
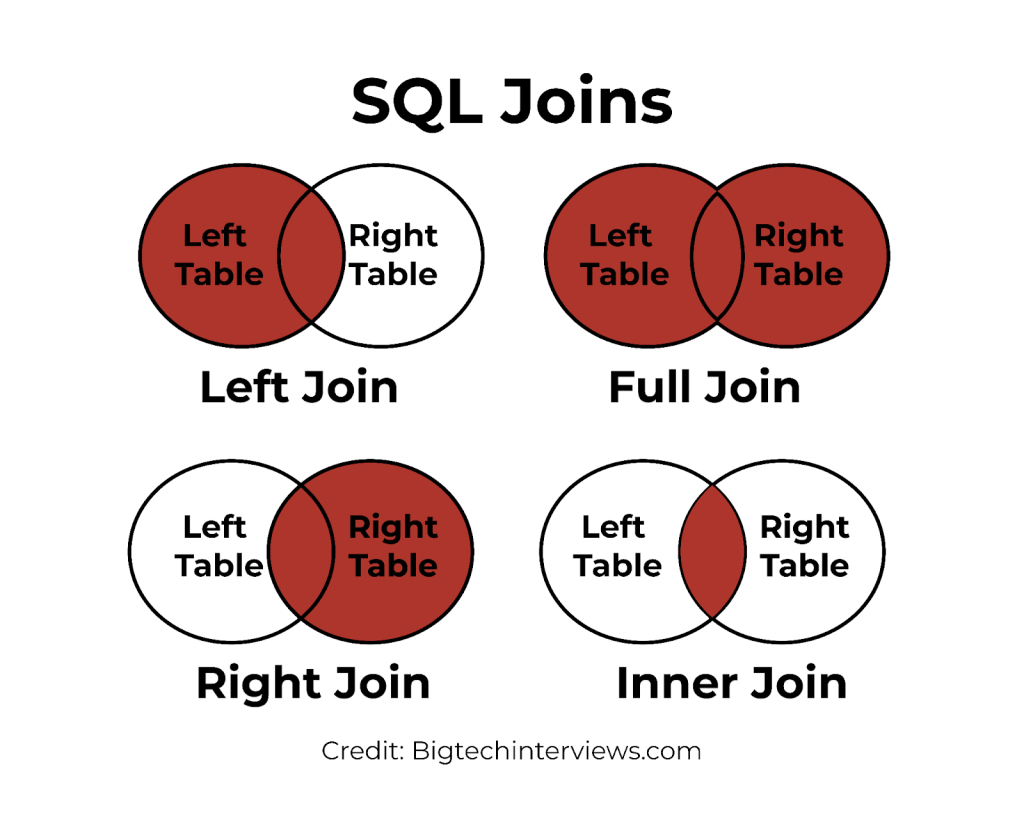
Types of Joins
The different types of joins include:
- Inner Join:
- Description: An inner join only returns the rows with a match in both tables. If a row in one table doesn’t have a corresponding row in the other table, it will not be included in the result.
- Use Case: Use an inner join to find records with matching entries in both tables.
- Left (Outer) Join:
- Description: A left join returns all rows from the left table (the first table listed in the join clause) and the matching rows from the right table.
- Use Case: Use a left join when you want to include all records from the primary table, even if there are no corresponding matches in the related table.
- Right (Outer) Join:
- Description: A right join is the opposite of a left join. It returns all rows from the right table and the matching rows from the left table. If there is no match, the result will include NULL values for the left table’s columns.
- Use Case: Use a right join when you want to include all records from the secondary table, even if there are no corresponding matches in the primary table.
- Full (Outer) Join:
- Description: A full join returns all rows when there is a match in either table. This means it combines the results of both left and right joins, including rows that have no match in either table, filling in NULLs where appropriate.
- Use Case: Use a full join when you must include all records from both tables, regardless of whether they have matching rows in the other table.
Example: Analyzing Promotion Effectiveness
Consider a scenario where the revenue department at Meta wants to analyze the effectiveness of their promotions. You might be asked to write a query to find the percentage of orders with a valid promotion applied. A promotion is considered valid if the promotion_id exists in the promotions table.
Sample Data:
Table: orders
+----------+--------+------------+-----------+----------+------------------+
|product_id|store_id|customer_id |promotion_id|units_sold|transaction_date |
+----------+--------+------------+-----------+----------+------------------+
|1         |10      |100         |1000       |1         |2019-01-01 9:00:00|
|1         |10      |200         |null       |2         |2019-01-01 9:00:00|
|1         |10      |300         |1001       |3         |2019-01-01 9:00:00|
|1         |10      |400         |1002       |3         |2019-01-01 9:00:00|
|2         |10      |500         |1003       |3         |2019-01-01 9:00:00|
|2         |10      |600         |null       |2         |2019-01-01 9:00:00|
|3         |10      |700         |null       |4         |2019-01-01 9:00:00|
|3         |10      |800         |null       |2         |2019-01-01 9:00:00|
|3         |20      |900         |null       |1         |2019-01-01 9:00:00|
|3         |20      |100         |1004       |1         |2019-01-01 9:00:00|
|4         |20      |200         |1005       |1         |2019-01-01 9:00:00|
|4         |20      |300         |1006       |4         |2019-01-01 9:00:00|
|4         |20      |400         |1006       |4         |2019-01-01 9:00:00|
|5         |20      |500         |1002       |2         |2019-01-01 9:00:00|
+----------+--------+------------+-----------+----------+------------------+
Table: promotions
+------------+
|promotion_id|
+------------+
|1001 |
|1002 |
|1003 |
|1004 |
|1005 |
|1006 |
+------------+SQL Query:
| SELECT ROUND(100.0 * COUNT(DISTINCT o.product_id, o.store_id, o.customer_id, o.promotion_id) / COUNT(*), 2) AS promotion_effectiveness FROM orders o LEFT JOIN promotions p ON o.promotion_id = p.promotion_id WHERE o.promotion_id IS NOT NULL; |
Output:
+-------------------------+
| promotion_effectiveness |
+-------------------------+
| 57.14                   |
+-------------------------+
Explanation:
This query uses a LEFT JOIN to combine the orders and promotions tables based on the promotion_id. It then calculates the percentage of orders with a valid promotion by comparing the number of orders with a promotion to the total number of orders.
By understanding and effectively applying different types of joins, you can manipulate and analyze data across multiple tables, enabling you to derive insights crucial for making data-driven decisions.
Window Functions: Leveraging Advanced SQL Techniques for Data Analysis
Mastering Window functions is critical for data engineers as they enable complex calculations across table rows while maintaining the context of individual records. These functions are particularly useful for tasks like ranking, running totals, moving averages, and other advanced data analysis operations without losing the granularity of your data.
What is a Window Function?
A window function is a type of SQL function that performs SQL calculations across a set of table rows related to the current row, but unlike aggregate functions, they do not collapse the rows into a single result. Instead, window functions enable you to keep the current rows intact while applying operations that consider a defined subset of data, known as the “window.”
Common Uses of Window Functions
Types and uses of window functions include:
- Ranking:
- Description: Window functions can assign ranks to rows within a data partition, such as ranking sales representatives based on quarterly sales.
- Use Case: Use ranking functions like RANK() or ROW_NUMBER() to order rows and assign ranks based on specific criteria.
- Running Totals:
- Description: Window functions can calculate cumulative totals, such as tracking a product’s cumulative sales over time.
- Use Case: Use running totals to understand how metrics like sales or revenue accumulate over time.
- Moving Averages:
- Description: Window functions can calculate averages over a rolling window of data, such as calculating a moving average of stock prices.
- Use Case: Use moving averages to smooth out short-term fluctuations and highlight longer-term trends.
Example: Calculating Factory Contribution to Total Storage Volume
Consider a scenario where Amazon wants to calculate the percentage of cubic feet of volume that each factory contributes to the company’s total storage. Window functions are ideal for this type of calculation, as they allow us to perform operations on subsets of data while maintaining the context of each factory’s contribution.
Sample Data:
Table: factory_inventory
+---------+---------+-------+
| factory | product | units |
+---------+---------+-------+
|ABC1     |XYZ      |3      |
|ABC2     |PQR      |1      |
|ABC3     |GHI      |2      |
|ABC3     |JKL      |5      |
|ABC2     |MNO      |2      |
|ABC2     |STU      |3      |
|ABC2     |AAA      |4      |
|ABC2     |VWX      |1      |
|ABC1     |VWX      |1      |
|ABC1     |ZYX      |17     |
|ABC1     |YYY      |13     |
+---------+---------+-------+
Table: product_dimension_inches
+-----+-----+-----+---------+
| W | L | H | product |
+-----+-----+-----+---------+
|12 |10 |8 |XYZ |
|4 |3 |3 |PQR |ΩΩΩ
|14 |11 |2 |GHI |
|8 |10 |12 |JKL |
|8 |10 |10 |MNO |
|8 |10 |10 |STU |
|8 |10 |10 |VWX |
|8 |10 |NULL |YYY |
+-----+-----+-----+---------+SQL Query:
| WITH volume_calculation AS ( SELECT f.factory, f.product, (p.W * p.L * p.H) AS cubic_feet FROM factory_inventory f JOIN product_dimension_inches p ON f.product = p.product WHERE p.H IS NOT NULL ) , total_volume AS ( SELECT SUM(cubic_feet * units) AS total_cubic_feet FROM volume_calculation ) SELECT factory, ROUND(100.0 * SUM(cubic_feet * units) / (SELECT total_cubic_feet FROM total_volume), 2) AS pct FROM volume_calculation GROUP BY factory; |
Output:
+---------+-------+
| factory | pct   |
+---------+-------+
| ABC2    | 34.71 |
| ABC3    | 38.87 |
| ABC1    | 26.41 |
+---------+-------+
Explanation:
In this query, we begin by using a Common Table Expression (CTE) named volume_calculation to calculate the cubic feet of volume for each product in each factory. The next CTE, total_volume, sums up the cubic feet for the entire company’s storage. Finally, the main query calculates the percentage of the total cubic feet each factory contributes using a window function.
This approach allows us to maintain the context of each factory’s data while performing calculations considering the overall company storage, making it a powerful method for advanced data analysis.
By mastering window functions, you can perform complex calculations essential for deep data insights, ensuring that your data engineering skills are versatile and effective in solving real-world challenges.
CTEs (Common Table Expressions) with Window Functions: Organizing Complex SQL Queries
Mastering CTEs combined with window functions is essential for handling complex SQL queries. These advanced SQL techniques empower data engineers to structure and organize intricate queries, making them easier to understand and maintain.
Let’s dive into CTEs and how they can effectively be used with window functions.
What is a CTE?
A Common Table Expression (CTE) is a temporary result set you can reference within a SELECT, UPDATE, or DELETE statement. CTEs are particularly useful for breaking down complex queries into more manageable parts, allowing you to write cleaner and more readable SQL code. They can be thought of as temporary views that exist only during the execution of a query.
How Does a CTE Work?
A CTE is defined using the WITH clause, followed by a query that generates the temporary result set. Subsequent queries can then reference this result set as if it were a table. CTEs are powerful tools for performing multi-step transformations and aggregations, especially when combined with window functions.
Common Uses of CTEs with Window Functions
Typical uses of CTEs with window functions include:
- Ranking and Row Numbering:
- Description: CTEs combined with window functions like RANK() or ROW_NUMBER() allow you to assign ranks or row numbers within data partitions.
- Use Case: Rank products within each factory based on the number of units sold.
- Aggregating Data Over Partitions:
- Description: CTEs can calculate aggregates, such as totals or averages, over specific data partitions while keeping individual rows intact.
- Use Case: Calculate the percentage of total sales contributed by each factory.
- Multi-Step Data Transformation:
- Description: CTEs enable you to perform complex, multi-step data transformations by breaking down the process into smaller, more manageable steps.
- Use Cases: Filter and rank products within each factory, then select the top-performing products.
Example: Find the Three Most Common Toys per Factory
Consider a scenario where you need to find the three most common toys per factory, ordered first by factory and then by the rank of the toys within each factory. CTEs and window functions are ideal for this task, as they allow us to perform complex ranking operations while keeping the data organized and readable.
Sample Data:
Table: factory_inventory
+---------+---------+-------+
| factory | product | units |
+---------+---------+-------+
| ABC1    | XYZ     | 3     |
| ABC2    | PQR     | 1     |
| ABC3    | GHI     | 2     |
| ABC3    | JKL     | 5     |
| ABC2    | MNO     | 2     |
| ABC2    | STU     | 3     |
| ABC2    | AAA     | 4     |
| ABC2    | VWX     | 1     |
| ABC1    | VWX     | 1     |
| ABC1    | ZYX     | 17    |
| ABC1    | YYY     | 13    |
+---------+---------+-------+
SQL Query:
| WITH ProductRanks AS ( SELECT factory, product, units, RANK() OVER (PARTITION BY factory ORDER BY units DESC) AS product_rank FROM factory_inventory ), TopProducts AS ( SELECT factory, product, units, product_rank FROM ProductRanks WHERE product_rank <= 3 ) SELECT factory, product, product_rank AS top3 FROM TopProducts ORDER BY factory ASC, top3 ASC; |
Output:
+---------+---------+------+
| factory | product | top3 |
+---------+---------+------+
| ABC1    | ZYX     | 1    |
| ABC1    | YYY     | 2    |
| ABC1    | XYZ     | 3    |
| ABC2    | AAA     | 1    |
| ABC2    | STU     | 2    |
| ABC2    | MNO     | 3    |
| ABC3    | JKL     | 1    |
| ABC3    | GHI     | 2    |
+---------+---------+------+
Explanation:
- Step 1: Create the ProductRanks CTE: This CTE calculates the rank of each product within each factory based on the number of units using the RANK() window function. The products are partitioned by factory and ordered by the number of units in descending order.
- Step 2: Create the TopProducts CTE: This CTE filters the results to include only the top 3 products per factory by selecting from the ProductRanks CTE and applying the condition WHERE product_rank <= 3.
- Step 3: Use the CTEs in the Main Query: The final query selects the top 3 products per factory from the TopProducts CTE and orders the results by factory and product rank.
Combining CTEs with window functions allows you to manage complex SQL queries more effectively, making them easier to read, maintain, and debug. This approach also allows you to perform advanced data analysis operations within a structured framework, such as ranking and filtering.
Your ability to handle these SQL tasks is crucial, and by honing these skills with real-world examples, you’ll be well-equipped to meet the challenges of your data engineer interview.
ETL/ELT Pipelines
Building and maintaining ETL (Extract, Transform, Load) or ELT (Extract, Load, Transform) pipelines is a fundamental skill for data engineers. These ELT/ETL pipelines move data from various sources into a data warehouse or other storage systems, ensuring the data is clean, structured, and ready for analysis.
- How would you design an ETL pipeline for a large e-commerce platform?
- Sample Answer Outline:
- Data Sources:
- Describe the different data sources, such as customer transactions, product catalogs, and user activity logs.
- Extraction:
- Explain how you would extract data from these sources, considering batch and real-time data ingestion.
- Transformation:
- Discuss the transformation process, including data cleaning, enrichment, and aggregation.
- Mention tools like Apache Spark, Python scripts, or SQL for these tasks.
- Loading:
- Describe the loading process into a data warehouse, such as Amazon Redshift, Google BigQuery, or a relational database.
- Mention any partitioning or indexing strategies to optimize performance.
- Monitoring and Maintenance:
- Explain how you would monitor the pipeline’s performance, handle errors, and ensure data quality over time.
- Data Sources:
- What are the key differences between building an ETL pipeline and an ELT pipeline? When would you choose one over the other?
- Sample Answer Outline:
- ETL Pipeline:
- Explain that in an ETL pipeline, data is transformed before it is loaded into the destination.
- This is suitable for scenarios where complex transformations are needed before data storage.
- ELT Pipeline:
- Discuss that data is first loaded into the destination and then transformed in an ELT pipeline.
- This process is ideal for handling large volumes of raw data that require flexible, on-demand transformations.
- Choosing Between the Two:
- Suggest choosing ETL when dealing with sensitive data that needs to be cleaned and standardized before storage.
- ELT might also be preferred when working with big data and cloud-based architectures, where storage is cheap, and transformations can be performed post-load.
- ETL Pipeline:
- Describe a situation where you had to optimize an existing ETL pipeline. What were the challenges, and how did you address them?
- Sample Answer Outline:
- Situation: Describe the original ETL pipeline, including any performance or scalability issues it faced.
- Challenges: Explain the specific challenges, such as slow processing times, bottlenecks during the transformation stage, or difficulties handling increased data volumes.
- Optimization Strategies: Discuss the strategies you implemented, such as parallel processing, data partitioning, or switching to a more efficient data transformation tool.
- Outcome: Share the positive impact of your optimizations, such as reduced processing times, increased pipeline stability, or the ability to handle larger datasets.
Building and maintaining efficient ELT pipelines is a fundamental skill for data engineers. These pipelines form the backbone of data integration processes, enabling the seamless movement and transformation of data across various systems.
By mastering ELT pipeline design and implementation, you’ll ensure that data is accurate, timely, and readily available for analysis, making you an indispensable asset to any data-driven organization.
Data Modeling
Understanding data modeling is vital for a data engineer as it forms the backbone of how data is structured, stored, and accessed. A well-designed data model can significantly improve the efficiency of data retrieval and analysis, making it a key area of focus during interviews.
Key Concepts
Several key concepts include:
- Schema Design: Understanding the differences between star schema, snowflake schema, and galaxy schema and knowing when to use each.
- Normalization and Denormalization: Techniques to optimize database design by reducing redundancy (normalization) or improving query performance (denormalization).
- Entity-Relationship Diagrams (ERDs): Using ERDs to visualize data relationships and structures.
- Fact and Dimension Tables: Differentiating between fact tables, which store quantitative data, and dimension tables, which store descriptive data.
Example Interview Questions
Several Interview questions include:
- How would you design a schema for a retail sales database?
- Sample Answer Outline:
- Key Entities:
- Identify primary entities such as customers, products, transactions, and promotions.
- Discuss additional entities like stores, suppliers, and categories if necessary.
- Fact and Dimension Tables:
- Suggest using a star schema, with the central fact table being the sales table and dimension tables for customers, products, stores, and Projections.
- Explain how each dimension table stores descriptive attributes related to the sales transactions.
- Indexing and Performance:
- Address the use of indexes on key columns like customer ID and product ID to speed up query performance.
- Discuss the importance of partitioning large tables like sales based on date or region for scalability.
- Key Entities:
- Explain the difference between a star schema and a snowflake schema. When would you choose one over the other?
- Sample Answer Outline:
- Star Schema:
- Define a star schema as having a central fact table connected to dimension tables, which are not normalized.
- Discuss its simplicity, ease of use, and faster query performance due to fewer joins.
- Snowflake Schema:
- Define a snowflake schema as an extension of the star schema, in which dimension tables are further normalized into multiple related tables.
- Mention its benefits in terms of reduced data redundancy and storage efficiency but with increased complexity and potentially slower query performance.
- Choosing Between the Two:
- Suggest using a star schema when query performance is critical and the data volume is manageable.
- Recommend a snowflake schema when storage optimization is necessary, especially in environments with complex queries and where the data structure requires deeper normalization.
- Star Schema:
- How would you model a database for a ride-sharing application like Uber?
- Sample Answer Outline:
- Key Entities and Relationships:
- Identify essential entities like users, drivers, rides, vehicles, payments, and locations.
- Discuss the relationships between these entities, such as many-to-many relationships between users and rides and one-to-many relationships between drivers and vehicles.
- Schema Design:
- Propose using a hybrid schema that combines relational and non-relational approaches, where relational tables handle structured data like User profiles and Rides. At the same time, a NoSQL database manages real-time location tracking and unstructured data.
- Real-time Data Considerations:
- Address the need for real-time data processing, using technologies like Kafka for data streaming and Cassandra or DynamoDB for real-time storage.
- Discuss how you would ensure the system’s scalability, allowing it to handle high volumes of concurrent transactions.
- Data Integrity and Consistency:
- Explain how you would ensure data integrity across the system, such as implementing ACID-compliant transactions for payment processing.
- Discuss eventual consistency in the context of distributed databases for real-time data and how you would manage potential conflicts.
- Key Entities and Relationships:
Data modeling is the blueprint of any successful data infrastructure. Your ability to craft well-structured, efficient models as a data engineer can set the stage for robust data management and insightful analysis.
Demonstrating a deep understanding of these principles in your interviews not only showcases your technical expertise but also highlights your strategic thinking in creating scalable and reliable data solutions.
System Design
System design is a critical aspect of data engineering, as it involves planning and structuring complex data systems that meet specific business requirements.
Essential Components of System Design
- Scalability:
- Definition: Scalability refers to a system’s ability to handle increased loads, whether by scaling vertically (adding more power to existing machines) or horizontally (adding more machines to the system).
- Why It Matters: As data volumes grow, a scalable system ensures that performance remains consistent without requiring a complete redesign.
- Example: Designing a system that can scale to handle peak traffic during major sales events for an e-commerce platform.
- Fault Tolerance:
- Definition: Fault tolerance is the ability of a system to continue operating properly after some of its components fail.
- Why It Matters: Ensuring your system can withstand failures without losing data or functionality is crucial for maintaining reliability.
- Example: Implementing data replication across multiple nodes in a distributed database ensures that data is not lost if one node fails.
- Data Consistency:
- Definition: Data consistency ensures that data remains accurate and consistent across different parts of a system.
- Why It Matters: Consistency is crucial for making reliable business decisions based on accurate data.
- Example: Using ACID (Atomicity, Consistency, Isolation, Durability) transactions in a database to ensure that all parts of a transaction are completed successfully before committing.
- Latency and Performance:
- Definition: Latency refers to the time delay experienced in a system, while performance relates to how efficiently a system processes requests.
- Why It Matters: Low latency and high performance are essential for delivering real-time data insights and ensuring a smooth user experience.
- Example: Optimizing query performance by using indexing and caching mechanisms in a database.
- Security and Compliance:
- Definition: Security involves protecting data from unauthorized access, while compliance ensures that the system meets industry regulations and standards.
- Why It Matters: Protecting sensitive data and ensuring compliance with regulations like GDPR or HIPAA is vital for any data-driven organization.
- Example: Implementing encryption for data at rest and in transit and ensuring access controls are in place.
Example Interview Questions
- How would you design a scalable data processing system for a social media platform?
- Sample Answer Outline:
- Scalability: Discuss using distributed systems and cloud-based services like AWS or GCP to scale horizontally.
- Data Storage: Mention NoSQL databases like Cassandra for handling large volumes of unstructured data.
- Real-time Processing: Explain how you would use Apache Kafka and Spark Streaming for processing real-time data.
- Fault Tolerance: Describe how you would implement data replication and backups to ensure fault tolerance.
- Describe a system you designed that had to meet strict data consistency requirements.
- Sample Answer Outline:
- Scenario: Briefly explain the context, such as a financial system where accurate transactions are critical.
- Consistency Mechanisms: Discuss the use of ACID transactions and distributed consensus algorithms like Paxos or Raft.
- Challenges: Highlight any challenges you faced, such as maintaining consistency across multiple data centers.
- Outcome: Share the results, such as achieving near-perfect consistency with minimal latency.
- What strategies would you use to reduce latency in a distributed database system?
- Sample Answer Outline:
- Caching: Explain using caching mechanisms like Redis to store frequently accessed data.
- Indexing: Discuss the implementation of indexes on critical database columns to speed up query processing.
- Load Balancing: Mention the use of load balancers to distribute requests evenly across servers.
- Data Partitioning: Describe how you would partition data to ensure that queries can be processed locally, reducing the need for cross-node communication.
By mastering system design, you’ll be able to build robust systems that meet the complex needs of modern data-driven businesses.
Big Data Technologies
Mastering big data technologies is crucial for any data engineer, as these tools and platforms enable the processing and analysis of vast amounts of data. Understanding how to work with key technologies like Hadoop, Spark, and Kafka will not only prepare you for technical challenges but also demonstrate your ability to handle large-scale data environments efficiently.
Key Tools and Platforms
Data engineers often use tools and platforms designed to manage, process, and analyze big data. Here are some of the most critical ones:
- Hadoop: A framework that allows for distributed storage and processing of large datasets across clusters of computers using simple programming models.
- Apache Spark: Known for its speed and ease of use, Spark is a unified analytics engine for big data processing, with built-in modules for streaming, SQL, machine learning, and graph processing.
- Kafka: A distributed streaming platform used to build real-time data pipelines and streaming applications.
These structured answers help to showcase your understanding of database design, normalization, and real-world application of these concepts in a data engineering interview.
Importance of Scalability and Real-Time Processing
Scalability is a primary concern when dealing with big data. The ability to scale horizontally, adding more machines to handle the increasing volume of data, is essential. Real-time processing is another critical aspect, especially for applications that require immediate insights from data as it is generated.
- Scalability: Ensures the system can handle increased data loads without compromising performance. Techniques like sharding and partitioning are often used to achieve scalability.
- Real-Time Processing: Involves processing data as it arrives to deliver instant results. This is particularly important in industries like finance and e-commerce, where timely data insights can be a competitive advantage.
Example Interview Questions
Several Interview questions include:
- How would you handle large-scale data processing using Hadoop or Spark?
- Sample Answer Outline:
- Data Processing Framework:
- Discuss the choice between Hadoop and Spark, depending on the requirements (e.g., batch processing with Hadoop, real-time or iterative processing with Spark).
- Explain how Hadoop’s MapReduce paradigm or Spark’s in-memory processing can handle large datasets efficiently.
- Data Storage:
- Mention using Hadoop’s HDFS (Hadoop Distributed File System) to store large data files across a distributed environment.
- For Spark, discuss how it can integrate with HDFS, S3, or other storage systems for accessing and processing data.
- Optimization Techniques:
- Highlight techniques like data partitioning, caching in Spark, and using optimized formats like Parquet or ORC to improve processing speed.
- Discuss how to leverage YARN or Mesos for resource management and scalability.
- Data Processing Framework:
- Describe a scenario where you had to optimize a big data pipeline.
- Sample Answer Outline:
- Initial Pipeline Setup:
- Provide a brief description of the original pipeline, including the tools and technologies used (e.g., Kafka for data ingestion, Spark for processing, and HDFS for storage).
- Identifying Bottlenecks:
- Discuss how you identified performance bottlenecks, such as slow data ingestion, inefficient processing, or storage limitations.
- Optimization Strategies:
- Explain specific optimizations, like increasing parallelism in Spark jobs, using Kafka’s partitioning to distribute load, or implementing data compression to reduce storage requirements.
- Mention any changes in data architecture, such as moving from batch to micro-batch processing or improving the data flow through streamlining ETL processes.
- Initial Pipeline Setup:
- What are the challenges of real-time data processing, and how would you address them?
- Sample Answer Outline:
- Key Challenges:
- Identify challenges like latency, data consistency, fault tolerance, and scalability in real-time data processing environments.
- Solutions for Latency and Consistency:
- Discuss strategies to minimize latency, such as using in-memory processing with Spark Streaming or Flink and ensuring data consistency with transactional systems or Kafka’s exactly-once semantics.
- Fault Tolerance:
- Explain how to implement fault tolerance using checkpointing in Spark Streaming, Kafka’s replication mechanism, and distributed processing frameworks that can recover from failures without data loss.
- Scalability Considerations:
- Address the requirement to scale the real-time processing system by distributing the workload across multiple nodes and utilizing cloud-based services for dynamic resource allocation.
- Key Challenges:
These tools are essential for managing and processing big data, and your ability to leverage them effectively will be a key factor in your interview.
Cloud Technologies
Cloud technologies have become a cornerstone of modern data engineering, enabling scalable, flexible, and cost-effective data solutions. As a data engineer, familiarity with popular cloud platforms such as AWS, Google Cloud Platform (GCP), and Microsoft Azure is crucial.
Essential Services For Data Engineering
Each cloud provider offers a robust suite of tools designed to handle the diverse and complex needs of data engineers. Understanding these services is integral to building and maintaining scalable data infrastructure.
Below, we’ll explore several core services these platforms offer that are integral to building and maintaining scalable data infrastructure.
- AWS: Services like Amazon S3 for storage, AWS Glue for ETL, Amazon Redshift for data warehousing, and AWS Lambda for serverless computing are widely used.
- GCP: Key services include BigQuery for data warehousing, Google Cloud Storage, Dataflow for stream and batch processing, and Google Kubernetes Engine (GKE) for containerized applications.
- Azure: Azure offers services such as Azure Data Lake Storage, Azure Synapse Analytics, Azure Databricks for big data processing, and Azure Functions for serverless computing.
Security and Compliance Considerations
Ensuring data security and compliance in the cloud is a top priority. This involves implementing encryption for data at rest and in transit, managing access controls with Identity and Access Management (IAM) tools, and adhering to regulatory requirements like GDPR or HIPAA.
Cloud platforms provide various security features; however, the data engineer is ultimately responsible for configuring and managing these correctly.
Example Interview Questions
- How would you design a scalable data pipeline on AWS?
- Sample Answer Outline:
- Service Selection:
- Discuss using Amazon S3 for storage, AWS Glue for ETL, and Amazon Redshift or Amazon RDS for data warehousing.
- Mention Lambda functions or EC2 instances for processing and transformation.
- Scalability Considerations:
- Explain how AWS auto-scaling groups can dynamically adjust the number of EC2 instances based on workload.
- Discuss the use of Amazon Kinesis for real-time data streaming and processing.
- Cost Management:
- Address optimizing costs using spot instances for non-critical workloads and reserved instances for steady-state operations.
- Monitoring and Optimization:
- Mention the use of CloudWatch for monitoring pipeline performance and identifying bottlenecks.
- Service Selection:
- What are the key differences between using on-premises and cloud-based data solutions?
- Sample Answer Outline:
- Scalability:
- On-premise solutions require significant upfront investment in hardware, while cloud solutions offer on-demand scalability.
- Cost:
- Cloud services follow a pay-as-you-go model, reducing capital expenditure, whereas on-premise solutions involve higher initial costs but lower long-term operational costs.
- Maintenance and Management:
- Cloud providers handle maintenance, updates, and security patches, while on-premise solutions require internal IT resources for these tasks.
- Flexibility:
- Cloud platforms provide greater flexibility in terms of service integration and innovation with the latest technologies.
- Scalability:
- How do you ensure data security in cloud environments?
- Sample Answer Outline:
- Encryption:
- Explain the use of encryption for data at rest using AWS KMS, GCP’s Cloud Key Management, or Azure’s Key Vault.
- Access Controls:
- Discuss implementing IAM roles and policies to enforce the principle of least privilege.
- Network Security:
- Mention using VPCs, security groups, and VPNs to protect data within cloud environments.
- Compliance Monitoring:
- Address how to use tools like AWS Config, GCP’s Security Command Center, or Azure Policy to ensure continuous compliance with industry standards.
- Encryption:
By mastering the essential services offered by major cloud platforms, you’ll be equipped to build resilient data systems that meet the demands of modern data engineering.
Cultural Fit and Soft Skills
While technical expertise is crucial for a data engineer, your success in an interview also depends on your ability to demonstrate strong cultural fit and soft skills. Employers are looking for candidates who possess not only the technical know-how but also the interpersonal skills, adaptability, and problem-solving abilities to thrive in a collaborative work environment.
Let’s explore several essential soft skills as well as the types of questions you might encounter in a data engineer interview.
- Communication Skills
Effective communication is essential for data engineers, especially when explaining complex technical concepts to non-technical stakeholders. Clear communication ensures that everyone on the team understands your work and its impact on broader business goals.
Example Interview Question: Can you describe when you had to explain a complex technical issue to a non-technical team member? How did you ensure they understood?
Sample Answer Outline:
- Situation: Briefly describe the context in which you had to communicate a complex issue.
- Task: Explain your role and the need for clear communication.
- Action: Discuss your strategies to simplify the technical details, such as analogies or visual aids.
- Result: Highlight the outcome, such as improved team understanding or better decision-making.
- Problem-Solving and Adaptability
The ability to troubleshoot issues, adapt to new technologies, and find creative solutions is vital in the fast-paced field of data engineering.
Example Interview Question: Tell me about when you encountered a significant technical challenge. How did you approach it, and what was the outcome?
Sample Answer Outline:
- Situation: Describe the technical challenge you faced, such as a system failure or a difficult data integration task.
- Task: Explain your role in resolving the issue.
- Action: Discuss the steps you took to troubleshoot and solve the problem, including any innovative solutions or tools you used.
- Result: Share the positive outcome, such as restoring system functionality, improving data accuracy, or completing the project on time.
- Team Collaboration
Data engineering projects often involve cross-functional teams, including data scientists, analysts, and business stakeholders. Effective collaboration is vital to ensuring that data solutions meet the needs of all stakeholders.
Example Interview Question: Describe a scenario when you worked closely with a team to achieve a common goal. What was your contribution, and how did the team succeed?
Sample Answer Outline:
- Situation: Set the scene by describing the project or goal your team was working toward.
- Task: Highlight your specific responsibilities within the team.
- Action: Detail how you collaborated with others, including any challenges you faced and how you overcame them.
- Result: Discuss the team’s success and how your contribution helped achieve the desired outcome.
- Time Management and Prioritization
Data engineers often juggle multiple tasks and projects. Effective time management and prioritization ensure you can meet deadlines and deliver high-quality work.
Example Interview Question: Can you explain how you managed competing priorities in a high-pressure situation?
Sample Answer Outline:
- Situation: Describe a situation where you had multiple high-priority tasks to manage.
- Task: Explain how you identified and prioritized the tasks.
- Action: Discuss your time management strategies, such as task delegation or setting up a clear timeline.
- Result: Highlight the successful completion of tasks and any positive feedback you received.
Mastering cultural fit and soft skills are as essential as technical expertise in a data engineering role. By preparing thoughtful, structured responses to interview questions, you can demonstrate your ability to communicate effectively, solve problems, collaborate with others, and manage your time efficiently. These skills will help you succeed in your interview and ensure long-term success in your career as a data engineer.
In Conclusion
Acing your data engineer interview requires a balanced blend of technical expertise, problem-solving abilities, and strong interpersonal skills. Your preparation should be thorough, focusing on mastering key technical skills like SQL, data modeling, and big data technologies, while also honing your ability to work collaboratively and adapt to new challenges.
Remember, it’s not just about showcasing what you know—it’s about demonstrating how to apply that knowledge to solve real-world challenges, contribute to team efforts, and drive success within a company.
As you prepare for your interview, continue refining your skills, practicing with real-world scenarios, and staying current with industry trends. This comprehensive approach will boost your confidence and increase your chances of securing the data engineering role you’re aiming for.
If you are looking to further enhance your skills or need personalized guidance, consider exploring our advanced resources at app.bigtechinterviews.com to give you that extra edge in your interview preparation.