


Many dream of securing a position as a data analyst at Google, thanks to its reputation for innovation, dynamic work culture, and the opportunity to work on impactful projects. However, the interview process for this role is known for being challenging, designed to identify candidates with the right mix of technical expertise, problem-solving abilities, and cultural fit.
As the demand for data-driven insights (as the foundation for data-driven innovation) grows, the role of data analysts at Google becomes increasingly vital. These professionals extract meaningful information from vast datasets to inform business strategies and enhance product development.
This guide is similar to the 33 Must-Know Data Analyst SQL Interview Questions and Answers and is designed to help you confidently navigate the Google Data Analyst interview process.
We’ll walk you through various interview stages, from the initial phone call to the onsite interviews, and provide insights into the types of questions you can expect.
You’ll also find tips on preparing effectively, including brushing up on key skills like SQL, Python, statistical analysis, and understanding Google’s unique culture. By the end of this guide, you’ll be well-equipped to tackle the interview process and move one step closer to landing your dream job at Google.
Understanding the Google Analyst Role
At Google, data analysts play a pivotal role in driving business strategies by extracting and interpreting data from various sources. These professionals collect, organize, and analyze vast datasets to provide actionable insights that inform decision-making processes.
Key Responsibilities
Data analysts at Google focus on several core responsibilities. They begin by ensuring accurate data collection and management from sources like Google Analytics and Google Ads. This involves developing and implementing robust data tracking strategies to capture relevant data aligned with the organization’s objectives.
In their analysis, they dive deep into large datasets to identify patterns and trends. By applying statistical methods, they draw meaningful insights that can drive business growth. Collaboration is also essential, as they work closely with cross-functional teams to define key performance indicators (KPIs) and develop measurement plans.
Once the data is analyzed, these analysts create reports and dashboards using tools such as Tableau and Power BI. Their goal is to present data clearly and clearly to both technical and non-technical stakeholders, ensuring that insights are effectively communicated and actionable.
Skills and Qualifications
To excel in this role, a solid technical foundation is crucial. Proficiency in SQL, Python, or R is necessary for handling and analyzing data—see our SQL Cheat Sheet: 2024 Edition for an in-depth guide to what’s what in SQL. Moreover, a solid understanding of statistical concepts like regression analysis and hypothesis testing is essential for accurate data interpretation.
Analytical skills are a must, enabling analysts to solve complex business problems and optimize processes. These skills are complemented by effective communication abilities, allowing them to convey technical concepts to non-technical audiences clearly and concisely.
Google values detail-oriented individuals who are adaptable and collaborative. These analysts must be precise in their work, open to learning new technologies, and capable of working well in team-oriented environments.
Unique Aspects of the Role at Google
Working at Google offers a unique and innovative environment. The company strongly emphasizes creativity, collaboration, and the integration of AI and machine learning technologies. This focus ensures that data analysts are constantly at the forefront of technological advancements.
The impact of a Google data analyst’s work is significant, affecting millions of users worldwide. Their insights directly contribute to business strategies, enhancing user experiences and driving Google’s mission forward.
In summary, the role of a Google data analyst is multifaceted, requiring a blend of technical expertise, analytical acumen, and effective communication skills. By excelling in these areas, Google data analysts can significantly influence the company’s strategic direction and contribute to its ongoing success.
Google Data Analyst Interview Process: What to Expect
The Google Data Analyst Interview process is similar to the Meta Data Engineer Interview process and is known for its rigor and comprehensiveness. Here’s an overview of what you can expect at each stage of the process:
- Initial Phone Interview
The journey begins with a 30-minute exploratory call with an HR representative or hiring manager. This conversation aims to understand your background, interests, and past project experiences. The interviewer will also assess your skills relevant to the data analyst role and provide information about Google, its culture, the specific team, and the job’s scope. To excel at this stage, it is vital to prepare responses for common behavioral and resume-based questions.
- Onsite Interview
If you pass the initial phone screening, you’ll be invited to the onsite interview, which typically consists of three to four one-on-one interview rounds, each lasting around 45 minutes. These rounds involve interviews with a hiring manager, team manager, and potentially a developer. Each interviewer will focus on different aspects of your capabilities, including:
- Technical Skills: You’ll face questions on SQL (including the 3 latest Google SQL interview questions), data analytics, and statistical concepts. You might be asked to write complex SQL queries, demonstrate data visualization skills, and discuss your knowledge of statistical methods.
- Product Sense: This aspect evaluates your ability to define key metrics and understand product analysis. Expect scenario-based questions that test your grasp of statistical concepts and coding skills.
- Behavioral and Cultural Fit: Google strongly emphasizes cultural alignment. The interview will assess how well you fit with Google’s attributes, such as teamwork, adaptability, and the unique quality of “Googliness.” Be prepared to discuss past experiences that highlight these traits.
- Interview Content
Throughout the interview process, Google evaluates candidates in the following key areas:
- SQL Proficiency: You’ll need to write advanced SQL queries (including elements such as Common Table Expressions and SQL Joins) to extract, transform, and analyze data.
- Data Analysis and Visualization: It is crucial to demonstrate your ability to perform data analysis and create compelling visualizations using tools like Tableau, Power BI, or programming languages such as Python or R.
- Statistical Concepts: Knowledge of statistical methods, including hypothesis testing, regression analysis, and probability, is frequently tested.
- Programming Skills: Proficiency in Python or R for data analysis, along with the ability to manipulate and clean data, is expected.
- Big Data Technologies: Depending on the role, understanding distributed data processing technologies like Hadoop, Spark, or BigQuery might be required.
- Behavioral Assessment
Google values candidates who demonstrate problem-solving skills, critical thinking, and the ability to work well in a team. During the behavioral interview, expect questions that explore your approach to challenges, decision-making processes, and collaboration experiences. The STAR (Situation, Task, Action, Result) method can be effective for structuring your responses.
Preparation tips include:
- Study the Role: Research the specific team and role you are applying for and understand how it supports Google’s overall goals.
- Brush up on Technical Skills: Gain proficiency in SQL (solving problems like those found on app.bigtechinterviews.com), Python, and data visualization tools. Review statistical concepts and practice solving real-world analytics problems.
- Practice Behavioral Questions: Reflect on past experiences and practice articulating them concisely using the STAR method.
- Mock Interviews: Conduct mock interviews to simulate the actual experience and improve your communication skills.
By understanding and preparing for these stages, you’ll be better equipped to navigate the Google Data Analyst interview process and showcase your skills and fit for the role.
Preparing for the Data Analyst Technical Interview at Google
Preparing for this technical interview requires a strategic approach, focusing on key technical areas and honing your problem-solving skills. Here are the essential topics and steps to guide your preparation:
- SQL Proficiency
Mastering SQL is imperative for excelling as a data analyst at Google. You will often need to extract, manipulate, and analyze large datasets from various databases, utilizing advanced SQL features such as joins, subqueries, UNIONs, and aggregate functions.
For example, you might be tasked with identifying trends in user behavior, which requires writing efficient queries to handle and process large volumes of data accurately.
In addition to writing queries, a deep understanding of database concepts and data modeling is vital. Data analysts at Google must be able to design and optimize databases to ensure efficient data storage and retrieval.
This includes knowledge of normalization techniques, indexing, and the ability to design schemas that support robust data analysis. Effective data modeling helps structure the data, making it easier to generate reports and conduct comprehensive analyses.
To illustrate the types of SQL questions you might encounter during your Google data analyst interview, consider the following examples:
1.1 Easy SQL Question
Imagine you are tasked with finding how many orders were placed by each registered customer. To find this answer, you must write a query to identify the number of orders placed by each registered customer.
The data tables used are:
Table: purchases
+-------------+------------+--------+------------+----------------+
| purchase_id | date       | amount | product_id | customer_name  |
+-------------+------------+--------+------------+----------------+
| 1           | 2024-04-01 | 50     | 101        | David          |
| 2           | 2024-04-02 | 30     | 102        | Emily          |
| 3           | 2024-04-03 | 20     | 101        | Michael        |
| 4           | 2024-04-04 | 40     | 100        | Emily          |
| 5           | 2024-04-05 | 60     | 102        | Guest          |
+-------------+------------+--------+------------+----------------+
Table: registered_customers
+-------------+---------------+------------+------------+---------+
| customer_id | customer_name | join_date | state | country |
+-------------+---------------+------------+------------+---------+
| 1001 | John | 2024-01-15 | California | USA |
| 1002 | Emily | 2024-02-20 | New York | USA |
| 1003 | David | 2024-03-10 | Texas | USA |
| 1004 | Sarah | 2024-04-05 | Florida | USA |
| 1005 | Michael | 2024-05-01 | Illinois | USA |
+-------------+---------------+------------+------------+---------+The SQL query is as follows:
| SELECT rc.customer_id, COUNT(p.purchase_id) AS number_of_orders FROM registered_customers rc JOIN purchases p ON rc.customer_name = p.customer_name GROUP BY rc.customer_id; |
In this example:
- FROM registered_customers rc: We start with the registered_customers table, aliasing it as rc.
- JOIN purchases p ON rc.customer_name = p.customer_name: We perform an inner join on the customer_name column to combine rows from registered_customers and purchases where the customer_name matches.
- SELECT rc.customer_id, COUNT(p.purchase_id) AS number_of_orders: We select the customer_id from the registered_customers table and count the number of purchase_id entries from the purchases table for each customer.
- GROUP BY rc.customer_id: We group the results by customer_id to ensure that the count of purchases is calculated for each registered customer.
Lastly, the output is:
Table: customer_orders
+-------------+------------------+
| customer_id | number_of_orders |
+-------------+------------------+
| 1002        | 2                |
| 1003        | 1                |
| 1005        | 1                |
+-------------+------------------+
This output shows the number of orders placed by each customer who is registered, helping to understand customer engagement and purchase behavior.
1.2 Medium SQL Question
Imagine you are tasked with finding the customer who provided the highest review score and received the most helpful votes for each product on each review date.
To find this answer, write a query identifying the highest review score and the most helpful votes for each product on each review date.
The sample data used is as follows:
Table: product_reviews
+------------+-----------+-------------+-------------------------------+
|customer_id | product_id| review_date | review_score | helpful_votes  |
+------------+-----------+-------------+--------------+----------------+
|301         |101        |2024-04-01   |4.5           | 12             |
|302         |102        |2024-04-01   |3.8           | 8              |
|303         |103        |2024-04-01   |4.2           | 10             |
|301         |101        |2024-04-02   |4.8           | 15             |
|302         |102        |2024-04-02   |3.5           | 7              |
|303         |103        |2024-04-02   |4.0           | 11             |
|301         |101        |2024-04-03   |4.2           | 13             |
|302         |102        |2024-04-03   |4.0           | 10             |
|303         |103        |2024-04-03   |4.5           | 14             |
+------------+-----------+-------------+--------------+----------------+
The SQL query is as follows:
| WITH RankedReviews AS ( SELECT customer_id, product_id, review_date, review_score, helpful_votes, DENSE_RANK() OVER ( PARTITION BY product_id, review_date ORDER BY review_score DESC, helpful_votes DESC ) AS rank FROM product_reviews ) SELECT customer_id, product_id, review_date, review_score, helpful_votes FROM RankedReviews WHERE rank = 1; |
The explanation is:
- Common Table Expression (CTE) RankedReviews:
- We use a CTE to create a subquery where we rank the reviews for each product on each review date based on review_score and helpful_votes.
- The DENSE_RANK() function assigns a rank starting at 1 for the highest score and most helpful votes, partitioning by product_id and review_date.
- Main Query:
- The main query selects only those rows from the RankedReviews CTE where the rank is 1.
- This ensures that only the highest-ranked reviews (based on review score and helpful votes) for each product on each review date are included in the result.
Lastly, the output is as follows:
+------------+-----------+-------------+--------------+----------------+
|customer_id | product_id| review_date | review_score | helpful_votes  |
+------------+-----------+-------------+--------------+----------------+
|301         |101        |2024-04-01   |4.5           | 12             |
|301         |101        |2024-04-02   |4.8           | 15             |
|303         |103        |2024-04-03   |4.5           | 14             |
+------------+-----------+-------------+--------------+----------------+
This output shows the customer who provided the highest review score and received the most helpful votes for each product on each review date, helping to understand customer engagement and review quality.
Note: Using DENSE_RANK() is beneficial in this scenario as it ensures that multiple top reviews (if tied) are included in the result. This approach highlights the most impactful customer reviews per product per day.
1.3 Advanced SQL Question
Imagine you are tasked with finding the customer who has spent the most on books in each genre. If there are ties, include all customers with the highest total spend. The result should include the genre, customer name, and the total spend for each customer ordered by genre ASC (ascending).
The sample data tables used are:
Table: books
+---+------------------------+-------------------+-------+----------------+-----+
|id |title                   |author             |genre  |publication_year|price|
+---+------------------------+-------------------+-------+----------------+-----+
|1  |The Great Gatsby        |F. Scott Fitzgerald|Fiction| 1925           |12.99|
|2  |To Kill a Mockingbird   |Harper Lee         |Fiction| 1960           |14.99|
|3  |1984                    |George Orwell      |Fiction| 1949           |9.99 |
|4  |The Catcher in the Rye  |J.D. Salinger      |Fiction| 1951           |11.99|
|5  |Pride and Prejudice     |Jane Austen        |Fiction| 1813           |10.99|
|6  |Little Women            |Louisa May Alcott  |Fiction| 1868           |8.99 |
|7  |The Hobbit              |J.R.R. Tolkien     |Fantasy| 1937           |13.99|
|8  |The Lord of the Rings   |J.R.R. Tolkien     |Fantasy| 1954           |25.99|
|9  |Harry Potter & the Philo|J.K. Rowling       |Fantasy| 1997           |17.99|
|10 |The Da Vinci Code       |Dan Brown          |Mystery| 2003           |14.99|
+---+------------------------+-------------------+-------+----------------+-----+
Table: orders
+---+----------+------------------+------------+--------------+
|id | book_id | customer_name | order_date | order_amount |
+---+----------+------------------+------------+--------------+
| 1 | 1 | John Smith | 2022-02-14 | 25.98 |
| 2 | 2 | Jane Doe | 2022-01-21 | 14.99 |
| 3 | 3 | Tom Brown | 2022-02-02 | 9.99 |
| 4 | 4 | Mary Johnson | 2022-01-05 | 11.99 |
| 5 | 5 | Mike Lee | 2022-02-28 | 21.98 |
| 6 | 6 | Sara Lee | 2022-01-31 | 8.99 |
| 7 | 7 | Peter Jackson | 2022-02-14 | 27.98 |
| 8 | 8 | Steven Spielberg | 2022-01-21 | 77.97 |
| 9 | 9 | George Lucas | 2022-02-02 | 35.98 |
| 10| 10 | Dan Brown | 2022-01-05 | 14.99 |
| 11| 1 | Alex Brown | 2022-02-28 | 12.99 |
| 12| 3 | Linda Green | 2022-01-31 | 19.98 |
| 13| 5 | Jason Williams | 2022-02-14 | 10.99 |
| 14| 7 | Julie Andrews | 2022-01-21 | 27.98 |
+---+----------+------------------+------------+--------------+The SQL query to achieve this is as follows:
| WITH GenreSpending AS ( SELECT b.genre, o.customer_name, SUM(o.order_amount) AS total_spend FROM books b JOIN orders o ON b.id = o.book_id GROUP BY b.genre, o.customer_name ), RankedSpending AS ( SELECT genre, customer_name, total_spend, DENSE_RANK() OVER (PARTITION BY genre ORDER BY total_spend DESC) AS rank FROM GenreSpending ) SELECT genre, customer_name, total_spend FROM RankedSpending WHERE rank = 1 ORDER BY genre ASC; |
The following explanation is relevant to this SQL query:
- Common Table Expression (CTE) GenreSpending:
- We first join the books and orders tables on book_id.
- We group by genre and customer_name, calculating the total spend for each customer in each genre using SUM(order_amount).
- Common Table Expression (CTE) RankedSpending:
- In this CTE, we rank the customers within each genre by their total spend using the DENSE_RANK() function. This function assigns a rank to each customer per genre, starting from 1 for the highest spender.
- Main Query:
- We select the customers with the highest total spend in each genre (where rank = 1) and order the results by genre in ascending order.
Lastly, the output is found in the following table:
+---------+------------------+-------------+
| genre   | customer_name    | total_spend |
+---------+------------------+-------------+
| Fantasy | Steven Spielberg | 77.97       |
| Fiction | John Smith       | 25.98       |
| Mystery | Dan Brown        | 14.99       |
+---------+------------------+-------------+
This output shows the customer who has spent the most on books in each genre, helping to understand spending patterns and customer preferences.
2. Data Analysis and Visualization
Mastery in data analysis and visualization is crucial for a data analyst at Google. These skills enable analysts to derive meaningful insights from large datasets and present them in an accessible and actionable format.
2.1 Data Analysis Techniques
Effective data analysis involves systematically exploring, cleaning, and modeling data. Google data analysts use different techniques to identify patterns, correlations, and trends. This process often includes:
- Exploratory Data Analysis (EDA): This involves summarizing the main characteristics of a dataset, often using visual methods. Tools like Python’s pandas and seaborn libraries or R’s ggplot2 package are commonly used.
- Data Cleaning: Ensuring the accuracy and quality of data by handling missing values, outliers, and inconsistencies. This step is essential for reliable analysis.
- Data Transformation: Converting data into a suitable format for analysis, such as normalization or aggregation.
2.2 Tools for Data Analysis and Visualization
Proficiency in using data visualization tools is essential for conveying insights effectively. Google data analysts commonly use the following tools:
- Tableau: A powerful tool for creating interactive and shareable dashboards. It allows users to connect to various data sources, perform complex queries, and intuitively visualize data.
- Power BI: Another robust tool for data visualization, offering similar functionalities to Tableau but often preferred for its seamless integration with Microsoft products.
- Python and R: Both programming languages offer extensive data analysis and visualization libraries. Python’s matplotlib, seaborn, plotly, and R’s ggplot2 and Shiny are popular for creating detailed and customizable visualizations.
2.3 Example Data Visualization Tasks
The following example illustrates the type of tasks you might encounter as a Google data analyst:
- Task: Visualize a company’s monthly sales data over the past year, highlighting trends and identifying seasonal patterns.
- Approach:
- Load the Data: Import any sales data into a pandas DataFrame in Python.
- Clean the Data: Handle any missing values or outliers that could skew the analysis.
- Transform the Data: Aggregate the sales data by month to get a clear view of monthly trends.
- Visualize the Data: Display the monthly sales trends using a line plot, highlighting any significant peaks or troughs.
The following code achieves these requirements using Python with matplotlib:
| import pandas as pd import matplotlib.pyplot as plt # Load the data sales_data = pd.read_csv(‘sales_data.csv’) # Clean the data (example of handling missing values) sales_data = sales_data.dropna() # Transform the data monthly_sales = sales_data.groupby(‘Month’)[‘Sales’].sum().reset_index() # Visualize the data plt.figure(figsize=(10, 6)) plt.plot(monthly_sales[‘Month’], monthly_sales[‘Sales’], marker=’o’) plt.title(‘Monthly Sales Data’) plt.xlabel(‘Month’) plt.ylabel(‘Sales’) plt.grid(True) plt.show() |
When executed, this code produces the following output:
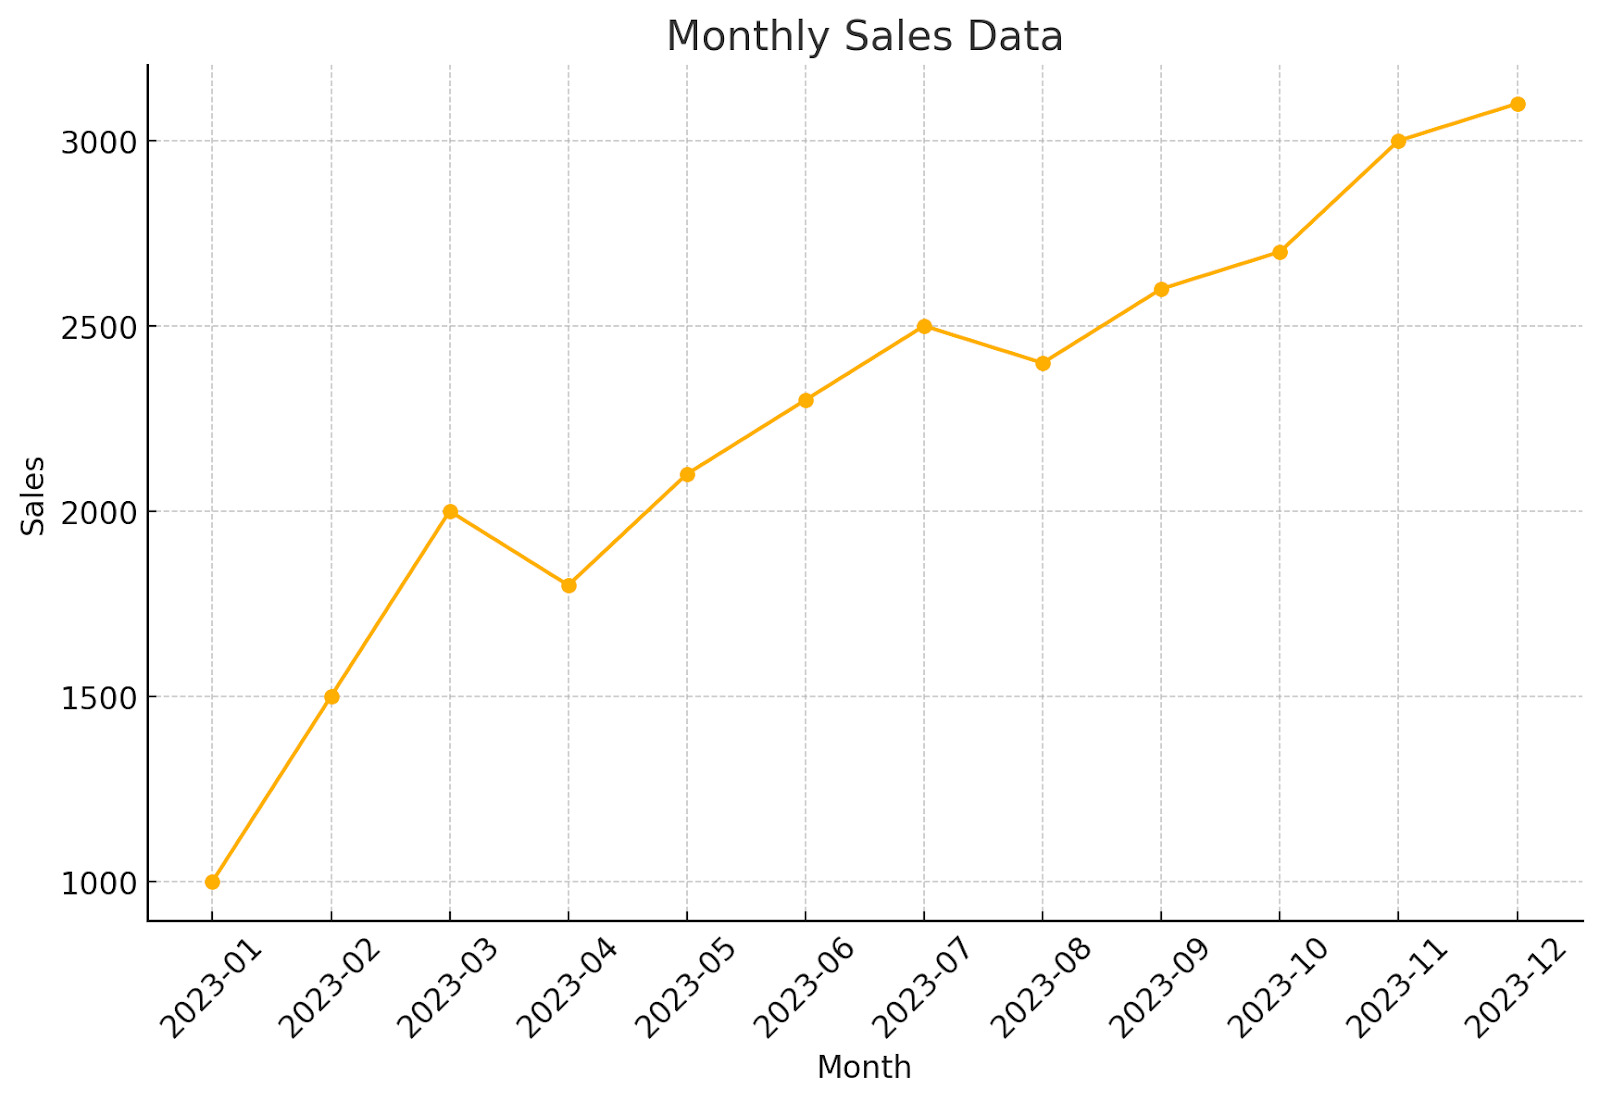
The plot shows the monthly sales data, illustrating the trend in sales over the year. Each point on the plot represents the total sales for a particular month, connected by a line to visualize the change over time. The x-axis shows the months, and the y-axis represents the sales amounts. The grid lines help in better understanding the data points and their progression.
3. Statistical Concepts
A solid understanding of statistical methods is essential for accurate data analysis and interpretation at Google. Analysts use these concepts to validate findings, make predictions, and support decision-making processes.
The key statistical methods used include:
- Hypothesis Testing: Used to determine if there is enough evidence to support a specific hypothesis about a dataset. Common tests include t-tests, chi-square tests, and ANOVA.
- Regression Analysis: A statistical technique for modeling the relationship between a dependent variable and one or more independent variables. Linear regression, logistic regression, and multiple regression are frequently used.
- Probability: Understanding probability distributions and their applications is vital for assessing risks and making informed predictions.
3.1 Application in Real-World Scenarios
Imagine you need to determine whether a new website design has improved user engagement. You might conduct an A/B test to compare the engagement metrics (like click-through rate and time spent on the page) between the old and new designs.
Here’s a simplified workflow for this test:
- Formulate the Hypothesis:
- Null Hypothesis (H0): There is no difference in engagement between the old and new designs.
- Alternative Hypothesis (H1): The new design improves user engagement.
- Collect the Data: Gather engagement metrics from a sample of users exposed to both designs.
- Perform the Test: Use a t-test to compare the means of engagement metrics between the two groups.
- Analyze the Results: If the p-value is less than the significance level (e.g., 0.05), reject the null hypothesis, suggesting that the new design has a statistically significant impact on user engagement.
By mastering these statistical concepts, you can effectively validate your analysis and provide accurate recommendations based on data-driven insights.
4. Programming Languages
Proficiency in programming languages like Python or R is crucial for a Google data analyst role. These languages are commonly used for data manipulation, analysis, and visualization due to their powerful libraries and ease of use.
Let’s explore how you can prepare for this aspect of the interview:
4.1 Python for Data Analysis
Python is a versatile language widely used in data analysis. Key libraries include:
- Pandas: For data manipulation and analysis.
- NumPy: For numerical operations.
- Matplotlib and Seaborn: For data visualization.
Example Question:
Describe how you would use Python to load, clean, and visualize a dataset containing sales data.
Provide an example using key Python libraries.
Answer:
To load, clean, and visualize a dataset containing sales data in Python, you can use the following steps:
- Load the data using Pandas:
| import pandas as pd # Load the data sales_data = pd.read_csv(‘sales_data.csv’) |
- Clean the data by handling missing values:
| # Clean the data (example of handling missing values) sales_data = sales_data.dropna() |
- Transform the data to calculate monthly sales:
| # Transform the data monthly_sales = sales_data.groupby(‘Month’)[‘Sales’].sum().reset_index() |
- Visualize the data using Matplotlib:
| import matplotlib.pyplot as plt # Visualize the data plt.figure(figsize=(10, 6)) plt.plot(monthly_sales[‘Month’], monthly_sales[‘Sales’], marker=’o’) plt.title(‘Monthly Sales Data’) plt.xlabel(‘Month’) plt.ylabel(‘Sales’) plt.grid(True) plt.show() |
Here is an example of the graph generated from this code. The graph visualizes the monthly sales data with markets for each data point.

4.2 R for Data Analysis
R is another powerful language for statistical computing and graphics. Key libraries include:
- dplyr: For data manipulation.
- ggplot2: For data visualization.
- tidyr: For data tidying.
- caret: For machine learning tasks.
- shiny: For building interactive web applications.
Example Question:
Describe how you would use R to load, clean, and visualize a dataset containing sales data. Provide an example using key R libraries.
Answer:
To load, clean, and visualize a dataset containing sales data in R, you can use the following steps:
- Load the data using read.csv:
| # Load necessary libraries library(dplyr) library(ggplot2) # Load the data sales_data <- read.csv(‘sales_data.csv’) |
- Clean the data by handling missing values:
| # Clean the data (example of handling missing values) sales_data <- na.omit(sales_data) |
- Transform the data to calculate monthly sales:
| # Transform the data monthly_sales <- sales_data %>% group_by(Month) %>% summarise(Sales = sum(Sales)) |
- Visualize the data using ggplot2:
| # Visualize the data ggplot(monthly_sales, aes(x = Month, y = Sales)) + geom_line() + geom_point() + ggtitle(‘Monthly Sales Data’) + xlab(‘Month’) + ylab(‘Sales’) + theme_minimal() |
In this example, the code loads sales data, cleans it by omitting missing values, transforms it to calculate monthly sales, and visualizes the data using ggplot2.
5. Data Manipulation and Cleaning Techniques
Effective data manipulation and cleaning are essential tasks for a data analyst. These processes ensure the dataset’s accuracy, completeness, and suitability for analysis.
Common data manipulation tasks include:
- Handling Missing Values: Remove rows/columns with missing values or add the missing values with mean/median/mode values.
- Removing Duplicates: Identify and remove duplicate rows.
- Data Transformation: Convert data types, normalize or standardize data, and create new features from existing data.
For example, in a sales dataset, you might need to impute missing values in the “purchase_amount” column, remove duplicate entries in the “customer_id” column, and convert date formats in the “transaction_date” column for consistency.
These techniques are crucial for maintaining data integrity and enabling meaningful insights.
Example Question:
Describe various techniques for data manipulation and cleaning that a data analyst might use, including handling missing values, removing duplicates, and transforming data.
Provide examples of when and how you would apply these techniques in a real-world scenario.
Answer:
Effective data manipulation and cleaning involve key techniques:
- Handle Missing Values:
- Removing Rows/Columns: If there are rows or columns with a significant amount of missing data, these can be removed, especially if the missing data is not critical to the analysis.
- Imputation: Replace missing values with the mean, median, or mode of the column. For instance, in a student scores dataset, missing scores could be replaced with the average score of the class.
- Remove Duplicates:
- Identifying and Removing Duplicates: Use functions to identify and remove duplicate rows. For example, in a customer database, duplicates might occur due to multiple entries of the same customer. Removing these ensures each customer is uniquely represented.
- Data Transformation:
- Converting Data Types: Convert data types to ensure consistency. For example, converting a data column from string to datetime format allows for proper date-based operations.
- Normalization or Standardization: Normalize data to bring all values into a common range or standardize data to have a mean of 0 and a standard deviation of 1. This is particularly useful in machine learning models to ensure each feature contributes equally.
- Creating New Features: Generate new features from existing data. For example, from a data column, create new features such as “day of the week,” “month,” or “quarter” to provide additional insights.
By understanding and mastering these data manipulation and cleaning techniques, candidates can ensure data quality and integrity, making them well-prepared to handle large-scale data challenges and contribute effectively to Google’s data-driven projects.
6. Machine Learning (Basic Concepts)
Understanding basic machine learning concepts is beneficial for a data analyst role. While not always required, familiarity with these concepts can give you an edge in your interview.
Key machine learning concepts include:
- Supervised Learning: Algorithms like linear regression, decision trees, and support vector machines.
- Unsupervised Learning: Algorithms like k-means clustering and principal component analysis (PCA).
- Model Evaluation: Metrics like accuracy, precision, recall, and F1-score.
- Cross-Validation: Techniques to assess model performance and prevent overfitting.
For instance, consider a housing price prediction scenario. You could use supervised learning to predict house prices based on features such as square footage, number of bedrooms, and location.
To evaluate the model, you would use metrics like Mean Squared Error (MSE) to measure the accuracy of your predictions and cross-validation techniques to ensure the model’s robustness and avoid overfitting.
The following Python code sample demonstrates a simple machine-learning task using Python’s Scikit-learn library.
It involves loading housing data, preparing features and the target variable, splitting the data into training and testing sets, training a linear regression model, making predictions, and evaluating the model using MSE.
| import pandas as pd from sklearn.model_selection import train_test_split from sklearn.linear_model import LinearRegression from sklearn.metrics import mean_squared_error # Load the data data = pd.read_csv(‘housing_data.csv’) # Prepare the data X = data[[‘feature1’, ‘feature2’, ‘feature3’]] y = data[‘price’] # Split the data into training and testing sets X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42) # Train a linear regression model model = LinearRegression() model.fit(X_train, y_train) # Make predictions y_pred = model.predict(X_test) # Evaluate the model mse = mean_squared_error(y_test, y_pred) print(f’Mean Squared Error: {mse}’) |
In this example, the code performs a series of steps to develop and evaluate a machine-learning model, illustrating the practical application of machine-learning concepts in data analysis.
Example Question:
Explain the differences between supervised and unsupervised learning and provide examples of algorithms used in each type.
Additionally, describe how you would evaluate the performance of a supervised learning model.
Answer:
Understanding the distinctions between different types of machine learning and their respective applications is crucial for effective data analysis.
- Supervised Learning: This involves training a model on a labeled dataset. Meaning the model learns from the input-output pairs. The goal is to predict the output from the new inputs. Examples of supervised learning algorithms include:
- Linear Regression: Used for predicting continuous values.
- Decision Trees: Used for both classification and regression tasks.
- Support Vector Machines: Used for classification tasks.
- Unsupervised Learning: This involves training a model on data without labeled responses. The goal is to uncover hidden patterns or intrinsic structures in the data. Examples of unsupervised learning algorithms include:
- K-Means Clustering: Used for partitioning data into distinct groups.
- Principal Component Analysis (PCA): Used for dimensionality reduction and identifying key components.
- Model Evaluation: To evaluate the performance of a supervised learning model, you can use the following metrics:
- Accuracy: The ratio of correctly predicted instances to the total instances (commonly used for classification tasks).
- Precision: The ratio of true positive predictions to the total positive predictions.
- Recall: The ratio of true positive predictions to the total actual positives.
- F1-Score: The harmonic mean of precision and recall, providing a balance between the two.
- Mean Squared Error (MSE): The average squared difference between predicted and actual values (commonly used for regression tasks).
By demonstrating knowledge of these machine learning concepts and their applications, candidates can showcase their analytical skills and readiness to handle complex data challenges at Google.
7. Big Data Technologies
In our data-driven world, understanding big data technologies is mandatory for data analysts, especially at a tech giant like Google. Big data technologies enable the processing and analysis of vast datasets that traditional data-processing software cannot handle.
Here are the key areas and concepts to focus on:
7.1 Distributed Data Processing
One of the core aspects of big data is the ability to process massive datasets across multiple machines. Technologies such as Hadoop and Apache Spark are essential for distributed data processing.
Hadoop uses a distributed file system (HDFS) to store data across multiple nodes, making it accessible for parallel processing. On the other hand, Spark provides an in-memory data processing engine, making it much faster for certain types of tasks than Hadoop.
Example Question:
For instance, an example question you might encounter is to explain how Apache Spark differs from Hadoop MapReduce and in what scenarios Spark is preferred over Hadoop.
Answer:
Apache Spark differs from Hadoop MapReduce in several ways:
- Speed: Spark processes data in memory, which makes it significantly faster than Hadoop MapReduce, which relies on disk-based processing.
- Ease of Use: Spark provides easy-to-use APIs in Java, Scala, Python, and R, whereas Hadoop requires more complex Java programming.
- Advanced Analytics: Spark includes libraries for SQL (Spark SQL), machine learning (MLlib), graph processing (GraphX), and steam processing (Spark Streaming), which are not available in Hadoop MapReduce.
- Use Cases: Spark is often preferred for iterative machine learning tasks, real-time data processing, and interactive data analytics. Hadoop is often used for batch processing tasks and when processing speed is less critical.
7.2 Data Storage and Management
Big data also involves managing and storing massive volumes of data. Google’s BigQuery, a fully managed, serverless data warehouse, enables super-fast queries using the processing power of Google’s infrastructure. Understanding how to leverage such tools to store, manage, and analyze big data is crucial.
Example Question:
An example question you might come across is to describe how Google Big Query handles data storage and querying and what its main advantages are.
Answer:
Google BigQuery handles data storage and querying using a columnar storage format and a distributed architecture. The main advantages of BigQuery include:
- Scalability: BigQuery can scale to handle large datasets with ease.
- Speed: It uses a highly optimized query engine and parallel processing to deliver fast query performance.
- Serverless: BigQuery eliminates the need for infrastructure management, as it is a fully managed service.
- Integration: it integrates seamlessly with other Google Cloud services and supports SQL, making it accessible for users familiar with SQL.
7.3 Real-Time Data Processing
Real-time data processing is crucial for applications that require immediate insights and actions. Apache Kafka is a popular technology used for building real-time data pipelines and streaming applications. It enables the real-time processing of data as it is generated, ensuring that information is quickly available for analysis and decision-making.
For instance, an eCommerce site might use Kafka to track user behavior and immediately recommend products based on the user’s browsing history. By streaming logs and user interactions through Kafka, organizations can analyze the data in real time to detect patterns, trigger alerts, or personalize user experiences.
Example Question:
In this section, a sample question could be: Explain the role of Apache Kafka in real-time data processing and provide a specific use case demonstrating its application.
Answer:
Apache Kafka is a distributed streaming platform used to build real-time data pipelines and streaming applications. It allows for the publishing and subscribing to streams of records in a fault-tolerant manner. The primary advantages of Apache Kafka include:
- Scalability: Kafka can scale horizontally, handling large volumes of data by distributing it across multiple brokers.
- Durability: Kafka provides reliable data storage with log replication across multiple nodes.
- Fault Tolerance: Kafka ensures high availability and resilience by replicating data and automatically handling broker failures.
By understanding and mastering these big data technologies, candidates can demonstrate their capability to handle large-scale data challenges and their readiness to contribute effectively to Google’s data-driven projects.
Additional Resources
To further assist you in your preparation, here are some valuable resources that can help you deepen your understanding and practice for the Google Data Analyst Interview:
- Amazon Data Analyst Interview Guide: Explore the Amazon Data Analyst Interview Guide to understand the types of questions and scenarios you might encounter in a similar role at Amazon. This guide can provide insights that are also relevant for your preparation at Google.
- Amazon SQL Interview Questions: Enhance your SQL skills by reviewing the Amazon SQL Interview Questions. This resource includes various SQL questions to help you practice writing and optimizing queries.
- Top 11 LeetCode Alternatives for Data Analysts and Data Scientists (2024 Edition): If you want additional coding practice, check out the Top 11 LeetCode Alternatives. These platforms offer a range of problems that can help you sharpen your coding and analytical skills.
- SQL joins are crucial for data analysis. The SQL Joins Guide comprehensively covers different join types and examples to help you master this important concept.
- SQL Case When: Learn how to use conditional logic in your SQL queries with the SQL Case When guide. This resource explains the syntax and provides examples to help you effectively apply this function in your data analysis tasks.
By leveraging these resources, you’ll be better prepared to tackle the technical and analytical challenges you may face during your Google Data Analyst interview.
Conclusion
Preparing for a data analyst role at Google requires a blend of technical expertise, analytical acumen, and a solid cultural fit. By mastering SQL, data analysis and visualization techniques, and understanding statistical concepts and programming languages, you’ll be well-equipped to tackle the challenges of the interview process.
Use the provided resources to deepen your knowledge and practice extensively. Remember, thorough preparation is vital to success. Approach the interview process with confidence and showcase your unique skills and experiences.
Good luck on your journey to becoming a Google Data Analyst!
Frequently Asked Questions (FAQs)
- What is the average salary for a Google Data Analyst?
The average base salary for a Google Data Analyst is approximately $132,569 per year. This figure can vary based on experience, location, and additional compensation like bonuses and stock options.
- How long should you prepare for the Google Data Analyst interview?
Preparation time can vary, but it is recommended that you spend at least 2-3 months preparing. This includes practicing Google SQL interview questions and Python skills, brushing up on statistical analysis, and understanding Google’s specific business and data needs.
- What are the key skills needed for a Google Data Analyst?
Critical skills include proficiency in SQL, Python, or R, a strong understanding of statistical methods, data visualization techniques, and practical communication skills. Familiarity with big data technologies and machine learning basics can also be beneficial.
- How do you approach a coding challenge in an interview?
When approaching a coding challenge, start by carefully reading the problem statement and identifying the inputs and expected outputs. Outline the logic and steps to solve the problem. Write clean and efficient code, test it with various cases, and explain your thought process to the interviewer.
- What are the best resources for SQL preparation?
Great resources for SQL preparation include books like “SQL for Data Scientists” by Renee M.P. Teate, online platforms such as Big Tech Interviews, Khan Academy, and Codecademy, as well as practicing with real-world datasets using tools like MySQL or PostgreSQL.