

Mastering SQL window functions is essential for anyone working with relational databases, especially data analysts, data scientists, SQL developers, and data engineers. These powerful functions allow you to perform calculations across a set of table rows that are related to the current row without collapsing the result set. This capability is invaluable for complex data analysis and reporting tasks.
In this comprehensive guide (as with all guides found on Big Tech Interviews), you will explore various types of window functions, learn how to use them effectively, and understand their performance implications. Whether you are preparing for an SQL interview, looking to enhance your data manipulation skills, or improving your database management capabilities, this guide will provide you with the necessary knowledge and tools.
By the end of this guide, you will have a solid understanding of Window Functions in SQL, including their syntax, use cases, and practical examples. You’ll be equipped to leverage these functions to streamline your data retrieval and analysis, ultimately making you more proficient in handling complex data tasks.
Overview of SQL Window Functions
SQL window functions allow you to perform calculations across a set of table rows that are related to the current row. Unlike aggregate functions, which return a single function for each group of rows, the window functions in SQL statements return a value for each row.
What are Window Functions in SQL?
An SQL window function operates on a set of rows and returns a single value for each row from the underlying query. These functions are extremely useful for a variety of tasks, such as calculating running totals, averages, and rankings.
Window functions in SQL are defined by the OVER clause, which determines the window or set of rows the function will operate on.
The OVER clause can include the following components:
- PARTITION BY: Divides the result set into partitions to which the window function is applied.
- ORDER BY: Specifies the order of rows within each partition.
- ROWS or RANGE: Defines the frame or subset of rows within the partition to perform the calculation.
Here is a basic example of a window function in SQL Server:
| SELECT employee_id, department_id, salary, AVG(salary) OVER (PARTITION BY department_id) AS avg_department_salary FROM employees; |
In this example:
- AVG(salary) Function: Calculates the average salary for each department.
- PARTITION BY department_id Clause: Divides the rows into partitions by department.
- AS avg_department_salary Clause: The average salary is calculated for each partition.
Key Components of SQL Window Functions
Understanding the essential components of SQL window functions is vital for performing advanced data analysis with precision and efficiency.
- PARTITION BY
The PARTITION BY clause is pivotal in dividing the result set into partitions, with each partition processed independently by the window function. Grouping rows on a common attribute allows for isolated calculations within each partition.
For instance, grouping sales data by employee enables the calculation of running totals for each individual, making it invaluable in scenarios requiring SQL ranking functions to rank data within specific groups.
- ORDER BY
The ORDER BY clause determines the sequence of rows within each partition. This ordering is essential for window functions that depend on the row sequence, such as running totals or moving averages. Specifying the order ensures logical and meaningful progression of calculations.
For example, ordering sales data by date within each employee partition facilitates calculating cumulative sales over time, a critical aspect in SQL data analysis functions where data order impacts the outcome.
- Frame Clause
The frame clause offers precise control over the subset of rows a window function operations on within each partition. This clause allows the definition of specific row ranges for calculations, improving query clarity and precision. Although the word “FRAME” is not explicitly used in SQL syntax, the concept is presented by components such as ROWS or RANGE, as well as the BETWEEN … AND clause within the OVER() clause.
Here are the frame clause’s components:
- ROWS or RANGE: Defines whether the frame is based on a number of rows (ROWS) or a range of values (RANGE).
- BETWEEN … AND: Sets the starting and ending points of a frame relative to the current row.
- UNBOUNDED PRECEDING: Covers all rows from the start of the partition up to the current row.
- UNBOUNDED FOLLOWING: Includes all rows from the current row to the partition’s endl
- CURRENT ROW: Refers specifically to the current row.
For instance, consider the following query using the frame clause:
| SELECT employee_id, sales_date, total_sales, SUM(total_sales) OVER (PARTITION BY employee_id ORDER BY sales_date ROWS BETWEEN 1 PRECEDING AND 1 FOLLOWING) AS moving_sum FROM sales_data; |
This query calculates a moving sum of total_sales for the current row, the previous row, and the next row within the same employee_id partition. Such control over row ranges enables detailed and accurate data analysis.
By mastering these key components—PARTITION BY, ORDER BY, and the frame clause—you can effectively leverage advanced SQL features like the SQL partition by clause and SQL cumulative sum to enhance your data analysis capabilities. These tools are essential for performing sophisticated and precise SQL queries.
Key Benefits of SQL Window Functions
Understanding the benefits of SQL window functions (together with all other SQL functions, clauses, and operators described in the SQL Cheat Sheet) can be applied in real-world scenarios helps highlight their benefits. Here are several specific applications where window functions provide significant advantages:
- Streamlining Time Series Analysis
Windows functions simplify time series analysis by enabling straightforward calculations for running totals, moving averages, and cumulative sums. For instance, instead of writing complex and cumbersome queries, you can use window functions to calculate the metrics efficiently across your dataset, making it easier to analyze trends and patterns over time.
- Enhancing Data Granularity
The flexibility of window functions allows you to perform calculations on a specific subset of rows while preserving the original row structure. This means you can compute metrics such as averages or rankings for each row without losing the detailed information in your dataset. For instance, calculating cumulative sales per customer becomes seamless, as window functions maintain the granularity of your data.
- Improving Query Performance
Window functions can increase the efficiency of your SQL queries by reducing the need for multiple joins and subqueries. This not only speeds up query execution but simplifies the overall design. For example, using window functions to compute running totals or ranks can streamline your query structure, making it more efficient and easier to read.
- Simplifying Complex Calculations
By allowing complex calculations to be performed within a single query, window functions improve the readability and maintainability of your SQL code. They eliminate the need for nested subqueries and multiple joins, resulting in cleaner and more understandable queries. For example, window functions simplify calculating detailed metrics, analyzing trends over time, or ranking data within a single query block.
Aggregate Window Functions in SQL
Aggregate window functions in SQL allow you to perform calculations such as SUM, Average, Min, Max, and Count over a set of rows related to the current row. These functions are essential for summarizing data without collapsing the result set, enabling detailed and dynamic data analysis.
Before we look at examples of the different aggregate window functions, here is the sample data table that we will use for all these examples:
Table: sales_data
+-------------+------------+-------------+
| employee_id | sales_date | total_sales |
+-------------+------------+-------------+
| 101         | 2024-01-01 | 500         |
| 102         | 2024-01-01 | 700         |
| 103         | 2024-01-01 | 600         |
| 101         | 2024-01-02 | 800         |
| 102         | 2024-01-02 | 750         |
| 103         | 2024-01-02 | 900         |
| 101         | 2024-01-03 | 600         |
| 102         | 2024-01-03 | 850         |
| 103         | 2024-01-03 | 700         |
+-------------+------------+-------------+- SUM
The SUM window function calculates the total sum of a numeric column for each row within a window of rows. Here’s an example based on the Apple SQL Question: Calculate the overall sales rankings for all employees found on Big Tech Interviews.
1.1 SQL Query:
| SELECT employee_id, SUM(total_sales) OVER (PARTITION BY employee_id) AS total_sales, RANK() OVER (ORDER BY SUM(total_sales) OVER (PARTITION BY employee_id) DESC) AS sales_rank FROM sales_data; |
1.2 Explanation:
- This query calculates the total sales for each employee and ranks them based on their total sales.
- SUM(total_sales) OVER (PARTITION BY employee_id) computes the sum of sales for each employee.
- RANK() OVER (ORDER BY SUM(total_sales) OVER (PARTITION BY employee_id) DESC) assigns a rank to each employee based on their total sales.
1.3 Output:
+-------------+-------------+------------+
| employee_id | total_sales | sales_rank |
+-------------+-------------+------------+
| 102         | 2300        | 1          |
| 103         | 2200        | 2          |
| 101         | 1900        | 3          |
+-------------+-------------+------------+
This output shows the total sales and corresponding sales rank for each employee. Employee 102 has the highest sales total of 2300, ranking first, followed by employee 103 with 2200 in second place, and employee 101 with 1900 in third place.
2. AVERAGE
The AVERAGE window function calculates the average value of a numeric column for each row within a window of rows. Here’s an example based on the sales data table to calculate the average sales for each employee.
2.1 SQL Query:
| SELECT employee_id, AVG(total_sales) OVER (PARTITION BY employee_id) AS average_sales FROM sales_data; |
2.2 Explanation:
- This query calculates the average sales for each employee.
- AVG(total_sales) OVER (PARTITION BY employee_id) computes the average sales for each employee.
2.3 Output:
+-------------+---------------+
| employee_id | average_sales |
+-------------+---------------+
| 101         | 633.33        |
| 102         | 766.67        |
| 103         | 733.33        |
+-------------+---------------+
This output shows the average sales for each employee. Employee 102 has the highest average sales, 766.67, followed by Employee 103, 733.33, and Employee 101, 633.33.
3. MIN
The MIN window function finds the minimum value of a numeric column for each row within a window of rows. Here’s an example of how to find the minimum sales for each employee.
3.1 SQL Query:
| SELECT employee_id, MIN(total_sales) OVER (PARTITION BY employee_id) AS min_sales FROM sales_data; |
3.2 Explanation:
- This query finds the minimum sales value for each employee.
- MIN(total_sales) OVER (PARTITION BY employee_id) computes the minimum sales for each employee.
3.3 Output:
+-------------+-----------+
| employee_id | min_sales |
+-------------+-----------+
| 101         | 500       |
| 102         | 700       |
| 103         | 600       |
+-------------+-----------+
This output shows the minimum sales for each employee. Employee 101 has the lowest minimum sales of 500, followed by Employee 103 with 600 and Employee 102 with 700.
4. MAX
The MAX window function finds the maximum value of a numeric column for each row within a window of rows. Here’s an example of finding the maximum sales for each employee.
4.1 SQL Query:
| SELECT employee_id, MAX(total_sales) OVER (PARTITION BY employee_id) AS max_sales FROM sales_data; |
4.2 Explanation:
- This query finds the maximum sales value for each employee.
- MAX(total_sales) OVER (PARTITION BY employee_id) computes the maximum sales for each employee.
4.3 Output:
+-------------+-----------+
| employee_id | max_sales |
+-------------+-----------+
| 101         | 800       |
| 102         | 850       |
| 103         | 900       |
+-------------+-----------+
This output shows the maximum sales for each employee. Employee 103 has the highest maximum sales of 900, followed by Employee 102 with 850 and Employee 101 with 800.
5. COUNT
The COUNT window function counts the number of rows for each row within a window of rows. Here’s an example that counts the number of sales entries for each employee.
5.1 SQL Query:
| SELECT employee_id, COUNT(total_sales) OVER (PARTITION BY employee_id) AS sales_count FROM sales_data; |
5.2 Explanation:
- This query counts the number of sales entries for each employee.
- COUNT(total_sales) OVER (PARTITION BY employee_id) computes the count of sales for each employee.
5.3 Output:
+-------------+-------------+
| employee_id | sales_count |
+-------------+-------------+
| 101         | 3           |
| 102         | 3           |
| 103         | 3           |
+-------------+-------------+
This output shows the number of sales entries for each employee. Each employee has made three sales entries during the observed period.
SQL window functions in SQL Server and other SQL platforms provide powerful tools for data analysis. By using aggregate window functions like SUM, AVERAGE, MIN, MAX, and COUNT, you can perform comprehensive data calculations without collapsing your result sets, enabling more dynamic and flexible data queries.
Ranking Window Functions in SQL
Ranking window functions in SQL assign a rank to each row within a partition of a result set. These functions are particularly useful for generating ordered results based on a specific column. Here’s how to use RANK(), DENSE_RANK(), and ROW_NUMBER() with practical examples.
Before we look at examples of the different ranking window functions, here is the sample data table that we will use for all these examples:
Table: factory_inventory
+---------+---------+-------+
| factory | product | units |
+---------+---------+-------+
|ABC1     |XYZ      |3      |
|ABC2     |PQR      |1      |
|ABC3     |GHI      |2      |
|ABC3     |JKL      |5      |
|ABC2     |MNO      |2      |
|ABC2     |STU      |3      |
|ABC2     |AAA      |4      |
|ABC2     |VWX      |1      |
|ABC1     |VWX      |1      |
|ABC1     |ZYX      |17     |
|ABC1     |YYY      |13     |
+---------+---------+-------+
Table: product_dimension_inches
+-----+-----+-----+---------+
| W | L | H | product |
+-----+-----+-----+---------+
|12 |10 |8 |XYZ |
|4 |3 |3 |PQR |
|14 |11 |2 |GHI |
|8 |10 |12 |JKL |
|8 |10 |10 |MNO |
|8 |10 |10 |STU |
|8 |10 |10 |VWX |
|8 |10 |NULL |YYY |
+-----+-----+-----+---------+- RANK()
The RANK() window function assigns a unique rank to each distinct row within a partition, with gaps in the ranking sequence when there are ties. Here’s an example based on an Amazon SQL question: Find the 3 most common toys per factory sourced from Big Tech Interviews.
1.1 SQL Query:
| SELECT factory, product, RANK() OVER (PARTITION BY factory ORDER BY units DESC) AS top3 FROM factory_inventory WHERE RANK() OVER (PARTITION BY factory ORDER BY units DESC) <= 3 ORDER BY factory ASC, top3 ASC; |
1.2 Explanation:
- This query finds the top 3 most common toys per factory.
- RANK() OVER (PARTITION BY factory ORDER BY units DESC) assigns a rank to each product within each factory based on the number of units, in descending order.
- The WHERE clause filters the results to include only the top 3 ranked products for each factory.
1.3 Output:
+-------+-------+----+
|factory|product|top3|
+-------+-------+----+
|ABC1   |ZYX    |1   |
|ABC1   |YYY    |2   |
|ABC1   |XYZ    |3   |
|ABC2   |AAA    |1   |
|ABC2   |STU    |2   |
|ABC2   |MNO    |3   |
|ABC3   |JKL    |1   |
|ABC3   |GHI    |2   |
+-------+-------+----+
This output shows the top 3 products for each factory, ranked by the number of units. The factory ABC1 has ZYX as the most common product, followed by YYY and XYZ.
- DENSE_RANK()
The DENSE_RANK() window function assigns a unique rank to each distinct row within a partition without gaps in the ranking sequence when there are ties. Here’s how to use DENSE_RANK():
2.1 SQL Query:
| SELECT factory, product, DENSE_RANK() OVER (PARTITION BY factory ORDER BY units DESC) AS top3 FROM factory_inventory WHERE DENSE_RANK() OVER (PARTITION BY factory ORDER BY units DESC) <= 3 ORDER BY factory ASC, top3 ASC; |
2.2 Explanation:
- This query finds the top 3 most common toys per factory.
- DENSE_RANK() OVER (PARTITION BY factory ORDER BY units DESC) assigns a dense rank to each product within each factory based on the number of units, in descending order.
- The WHERE clause filters the results to include only the top 3 ranked products for each factory.
2.3 Output:
+-------+-------+----+
|factory|product|top3|
+-------+-------+----+
|ABC1   |ZYX    |1   |
|ABC1   |YYY    |2   |
|ABC1   |XYZ    |3   |
|ABC2   |AAA    |1   |
|ABC2   |STU    |2   |
|ABC2   |MNO    |3   |
|ABC3   |JKL    |1   |
|ABC3   |GHI    |2   |
+-------+-------+----+
This output shows the top 3 products for each factory, ranked by the number of units, without gaps in the ranking sequence. The results are the same as with RANK() since there are no ties in the unit counts.
- ROW_NUMBER()
The ROW_NUMBER() window function assigns a unique sequential integer to rows within a partition of a result set. Here’s how to use ROW_NUMBER():
3.1 SQL Query:
| SELECT factory, product, ROW_NUMBER() OVER (PARTITION BY factory ORDER BY units DESC) AS top3 FROM factory_inventory WHERE ROW_NUMBER() OVER (PARTITION BY factory ORDER BY units DESC) <= 3 ORDER BY factory ASC, top3 ASC; |
3.2 Explanation:
- This query finds the top 3 most common toys per factory.
- ROW_NUMBER() OVER (PARTITION BY factory ORDER BY units DESC) assigns a unique sequential integer to each product within each factory based on the number of units in descending order.
- The WHERE clause filters the results to include only the top 3 ranked products for each factory.
3.3 Output:
+-------+-------+----+
|factory|product|top3|
+-------+-------+----+
|ABC1   |ZYX    |1   |
|ABC1   |YYY    |2   |
|ABC1   |XYZ    |3   |
|ABC2   |AAA    |1   |
|ABC2   |STU    |2   |
|ABC2   |MNO    |3   |
|ABC3   |JKL    |1   |
|ABC3   |GHI    |2   |
+-------+-------+----+
This output shows the top 3 products for each factory, ranked by the number of units, with each product assigned a unique sequential rank. The results are the same as those of RANK() and DENSE_RANK() since there are no ties in the unit counts.
Ranking window functions in SQL, such as RANK(), DENSE_RANK(), and ROW_NUMBER(), provide powerful tools for ordering and ranking your data. These functions can quickly generate ordered results based on specific columns, enabling more detailed and insightful data analysis.
Value Window Functions in SQL
Value WIndow functions in SQL efficiently access data from other rows within your result set, eliminating the need for complex self-joins. These functions, including LEAD, LAG, FIRST_VALUE, and LAST_VALUE, enable sophisticated data analysis and comparisons. Here’s how to use these functions.
Before we look at examples of the different value window functions in SQL, here is the sample data table that we will use for all these examples:
SQL Schema:
Table: user_transactions
+-------------+-----------+--------------------+
| Column Name | Type      | Description        |
+-------------+-----------+--------------------+
| user_id     | int       | User ID            |
| trans_date  | date      | Transaction Date   |
| amount      | decimal   | Transaction Amount |
+-------------+-----------+--------------------+
Example Data:
Table: user_transactions
+--------+------------+--------+
| user_id| trans_date | amount |
+--------+------------+--------+
| 1      | 2024-01-01 | 100    |
| 1      | 2024-01-02 | 150    |
| 1      | 2024-01-03 | 200    |
| 2      | 2024-01-01 | 50     |
| 2      | 2024-01-03 | 75     |
| 2      | 2024-01-04 | 125    |
| 3      | 2024-01-02 | 80     |
| 3      | 2024-01-03 | 90     |
| 3      | 2024-01-05 | 120    |
+--------+------------+--------+- LEAD
The LEAD function provides access to a row at a specified physical offset following a current row within a partition. In other words, you can retrieve data from rows that come after the current row alongside the current row, making it particularly useful for comparing data from current rows with future rows, identifying trends, calculating differences over time, or generating forward-looking metrics.
1.1 SQL Query:
| SELECT user_id, trans_date, amount, LEAD(amount, 1) OVER (PARTITION BY user_id ORDER BY trans_date) AS next_amount FROM user_transactions; |
1.2 Explanation:
- This query retrieves the next transaction amount for each user.
- LEAD(amount, 1) OVER (PARTITION BY user_id ORDER BY trans_date) fetches the amount from the next transaction date for each user.
1.3 Output:
+--------+------------+--------+-------------+
| user_id| trans_date | amount | next_amount |
+--------+------------+--------+-------------+
| 1      | 2024-01-01 | 100    | 150         |
| 1      | 2024-01-02 | 150    | 200         |
| 1      | 2024-01-03 | 200    | NULL        |
| 2      | 2024-01-01 | 50     | 75          |
| 2      | 2024-01-03 | 75     | 125         |
| 2      | 2024-01-04 | 125    | NULL        |
| 3      | 2024-01-02 | 80     | 90          |
| 3      | 2024-01-03 | 90     | 120         |
| 3      | 2024-01-05 | 120    | NULL        |
+--------+------------+--------+-------------+
This output shows each user’s current transaction amount and subsequent transaction amount. For example, user 1 has a next transaction amount of 150 after the transaction on 2024-01-01.
- LAG
The LAG function provides access to a row at a specified physical offset before the current row within the partition. This allows you to retrieve data from preceding rows while still displaying the current row, making it particularly useful for comparing current and previous rows.
This function is often used in SQL analytical functions to identify trends, calculate differences between consecutive records, and perform comparative analyses within the dataset.
2.1 SQL Query:
| SELECT user_id, trans_date, amount, LAG(amount, 1) OVER (PARTITION BY user_id ORDER BY trans_date) AS prev_amount FROM user_transactions; |
2.2 Explanation:
- This query retrieves the previous transaction amount for each user.
- LAG(amount, 1) OVER (PARTITION BY user_id ORDER BY trans_date) fetches the amount from the previous transaction date for each user.
2.3 Output:
+--------+------------+--------+-------------+
| user_id| trans_date | amount | prev_amount |
+--------+------------+--------+-------------+
| 1      | 2024-01-01 | 100    | NULL        |
| 1      | 2024-01-02 | 150    | 100         |
| 1      | 2024-01-03 | 200    | 150         |
| 2      | 2024-01-01 | 50     | NULL        |
| 2      | 2024-01-03 | 75     | 50          |
| 2      | 2024-01-04 | 125    | 75          |
| 3      | 2024-01-02 | 80     | NULL        |
| 3      | 2024-01-03 | 90     | 80          |
| 3      | 2024-01-05 | 120    | 90          |
+--------+------------+--------+-------------+
This output shows the current transaction amount and the previous transaction amount for each user. For example, user 1 has a previous transaction amount of 100 before the transaction on 2024-01-02.
- FIRST_VALUE
The FIRST_VALUE function returns the first value in an ordered set of values within a partition. This function is often used in SQL ranking functions to identify the first occurrence of a value within a partition.
By using FIRST_VALUE, you can retrieve the initial value in a specified order, which is useful for tasks such as finding the earliest transaction date, the initial status of a process, or the starting point of a sequence. This function helps perform detailed data analysis and reporting by allowing you to capture the starting value of a dataset segment.
3.1 SQL Query:
| SELECT user_id, trans_date, amount, FIRST_VALUE(amount) OVER (PARTITION BY user_id ORDER BY trans_date) AS first_amount FROM user_transactions; |
3.2 Explanation:
- This query retrieves the first transaction amount for each user.
- FIRST_VALUE(amount) OVER (PARTITION BY user_id ORDER BY trans_date) fetches the first transaction amount for each user.
3.3 Output:
+--------+------------+--------+-------------+
| user_id| trans_date | amount | first_amount|
+--------+------------+--------+-------------+
| 1      | 2024-01-01 | 100    | 100         |
| 1      | 2024-01-02 | 150    | 100         |
| 1      | 2024-01-03 | 200    | 100         |
| 2      | 2024-01-01 | 50     | 50          |
| 2      | 2024-01-03 | 75     | 50          |
| 2      | 2024-01-04 | 125    | 50          |
| 3      | 2024-01-02 | 80     | 80          |
| 3      | 2024-01-03 | 90     | 80          |
| 3      | 2024-01-05 | 120    | 80          |
+--------+------------+--------+-------------+
This output shows the first transaction amount for each user. For example, user 1 has a first transaction amount of 100 on 2024-01-01.
- LAST_VALUE
The LAST_VALUE function returns the last value in an ordered set of values within a partition. This function is commonly used with the SQL PARTITION BY clause to obtain the most recent or last value within each partition.
Using LAST_VALUE, you can retrieve the final value in a specified order, which is useful for tasks such as finding the most recent transaction amount, the last recorded status of a process, or the ending point of a sequence.
This function is valuable for time series analysis and generating reports requiring the latest data within grouped segments. It helps capture the end value of a dataset segment, enabling more comprehensive and insightful data analysis.
4.1 SQL Query:
| SELECT user_id, trans_date, amount, LAST_VALUE(amount) OVER (PARTITION BY user_id ORDER BY trans_date ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING) AS last_amount FROM user_transactions; |
4.2 Explanation:
- This query retrieves the last transaction amount for each user.
- LAST_VALUE(amount) OVER (PARTITION BY user_id ORDER BY trans_date ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING) fetches the last transaction amount for each user.
4.3 Output:
+--------+------------+--------+------------+
| user_id| trans_date | amount | last_amount|
+--------+------------+--------+------------+
| 1      | 2024-01-01 | 100    | 200        |
| 1      | 2024-01-02 | 150    | 200        |
| 1      | 2024-01-03 | 200    | 200        |
| 2      | 2024-01-01 | 50     | 125        |
| 2      | 2024-01-03 | 75     | 125        |
| 2      | 2024-01-04 | 125    | 125        |
| 3      | 2024-01-02 | 80     | 120        |
| 3      | 2024-01-03 | 90     | 120        |
| 3      | 2024-01-05 | 120    | 120        |
+--------+------------+--------+------------+
This output shows the last transaction amount for each user. For example, user 1 has a last transaction amount of 200 on 2024-01-03.
Value window functions like LEAD, LAG, FIRST_VALUE, and LAST_VALUE are powerful tools for accessing data from different rows within the same result set. These SQL window functions provide sophisticated data analysis capabilities and can be particularly useful for time series data or any dataset where the order of rows matters.
By mastering these functions, you can improve your ability to perform complex data analysis and generate meaningful insights.
Advanced SQL Window Functions
Advanced SQL window functions like PERCENT_RANK, NTILE, CUME_DIST, and NTH_VALUE are powerful tools for more complex data analysis and manipulation. These functions allow you to perform sophisticated calculations and partitioning, making them invaluable for handling large datasets and generating detailed insights.
This section explores how to use these functions to distribute data into groups, calculate relative ranks, and retrieve specific values within an ordered set.
Before we look at examples of the different value window functions in SQL, here is the sample data table (taken from Big Tech Interviews’ DoorDash SQL Question: Bottom 50% of dashers) that we will use for all these examples:
SQL Schema:
Table: dashers
+------------+---------+
|Column Name |Type     |
+------------+---------+
|id          |int      |
|first_name  |var      |
|last_name   |var      |
|email       |var      |
+------------+---------+
Table: timesheet_by_day
+------------+---------+
|Column Name |Type |
+------------+---------+
|dasher_id |int |
|hours_worked|int |
|pay_received|dec |
|date |date |
+------------+---------+Sample Data:
Table: dashers
+---+----------+---------+--------------------+
|id |first_name|last_name|email               |
+---+----------+---------+--------------------+
|1  |David     |Davis    |david.davis@dash.com|
|2  |Mary      |Mills    |mary.mills@dash.com |
|3  |Fred      |French   |fred.french@dash.com|
|4  |Greg      |German   |greg.german@dash.com|
|5  |Simon     |Smith    |simon.smith@dash.com|
+---+----------+---------+--------------------+
Table: timesheet_by_day
+---------+------------+------------+-----------------+
|dasher_id|hours_worked|pay_received|date |
+---------+------------+------------+-----------------+
|1 |8 |100 |current_date - 31|
|1 |8 |20 |current_date - 20|
|2 |2 |16 |current_date - 15|
|3 |1 |15 |current_date - 2 |
|4 |1 |16 |current_date - 20|
+---------+------------+------------+-----------------+- PERCENT_RANK
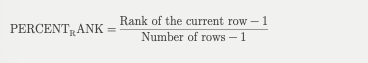
The PERCENT_RANK function calculates the relative rank of a row within a group of rows. The rank is expressed as a percentage, ranging from 0 to 1, representing the relative position of a value in a dataset. This function is useful for identifying the relative standing of values in a dataset, which can be particularly valuable for performance analysis, grading systems, and any scenario where relative ranking is important.
PERCENT_RANK is calculated as follows:
For example, Let’s say we want to target door dashers who are in the bottom 50th percentile of total pay per hour in the last 30 days with a promotion. The following query identifies these dashers along with their email addresses.
1.1 SQL Query:
| WITH total_pay AS ( SELECT dasher_id, SUM(pay_received) / SUM(hours_worked) AS pay_per_hour FROM timesheet_by_day WHERE date >= current_date – 30 GROUP BY dasher_id ) SELECT d.first_name, d.last_name, d.email, PERCENT_RANK() OVER (ORDER BY tp.pay_per_hour) AS percent_rank FROM total_pay tp JOIN dashers d ON tp.dasher_id = d.id WHERE PERCENT_RANK() OVER (ORDER BY tp.pay_per_hour) <= 0.5 ORDER BY tp.pay_per_hour; |
1.2 Explanation:
- The CTE total_pay calculates the pay per hour for each dasher in the last 30 days.
- PERCENT_RANK() OVER (ORDER BY tp.pay_per_hour) calculates the relative rank of each dasher within the dataset, expressed as a percentage.
- The WHERE clause filters the results to include only those dashers in the bottom 50th percentile.
1.3 Output:
+-----------+----------+--------------------+--------------+
|first_name |last_name |email               | percent_rank |
+-----------+----------+--------------------+--------------+
|David      |Davis     |david.davis@dash.com| 0.000        |
|Mary       |Mills     |mary.mills@dash.com | 0.250        |
|Fred       |French    |fred.french@dash.com| 0.500        |
+-----------+----------+--------------------+--------------+
This output shows the relative rank of each dasher based on their pay per hour, with only those in the bottom 50th percentile included. For example, David Davis has a PERCENT_RANK of 0.000, indicating he has the lowest pay per hour in the dataset, while Fred French has a PERCENT_RANK of 0.500, placing him at the midpoint of the distribution.
The PERCENT_RANK function makes it easy to determine the relative position of each value within a group, which is particularly useful for comparative analysis and performance evaluation.
- CUME_DIST
The CUME_DIST (cumulative distribution) function calculates the cumulative distribution of a value in a group of values. It returns a value between 0 and 1, representing the proportion of rows with values less than or equal to the current row’s value.
This function is useful for understanding the relative standing of a value within a dataset, such as determining how a score compares to others in a group.
CUME_DIST is calculated as follows:
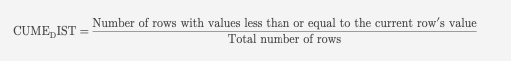
For example, imagine we want to target DoorDash dashers in the bottom 50th percentile of total pay per hour in the last 30 days with a promotion. The following query identifies these dashers along with their email addresses.
2.1 SQL Query:
| WITH total_pay AS ( SELECT dasher_id, SUM(pay_received) / SUM(hours_worked) AS pay_per_hour FROM timesheet_by_day WHERE date >= current_date – 30 GROUP BY dasher_id ) SELECT d.first_name, d.last_name, d.email, CUME_DIST() OVER (ORDER BY tp.pay_per_hour) AS cumulative_dist FROM total_pay tp JOIN dashers d ON tp.dasher_id = d.id WHERE CUME_DIST() OVER (ORDER BY tp.pay_per_hour) <= 0.5 ORDER BY tp.pay_per_hour; |
2.2 Explanation:
- The CTE total_pay calculates the pay per hour for each dasher in the last 30 days.
- CUME_DIST() OVER (ORDER BY tp.pay_per_hour) calculates the cumulative distribution of each dasher within the dataset, expressed as a proportion.
- The WHERE clause filters the results to include only those dashers in the bottom 50th percentile.
2.3 Output:
+-----------+----------+--------------------+------------------+
|first_name |last_name |email               | cumulative_dist  |
+-----------+----------+--------------------+------------------+
|David      |Davis     |david.davis@dash.com| 0.200            |
|Mary       |Mills     |mary.mills@dash.com | 0.400            |
|Fred       |French    |fred.french@dash.com| 0.600            |
+-----------+----------+--------------------+------------------+
This output shows the cumulative distribution of each dasher based on their pay per hour, with only those in the bottom 50th percentile included. For example, David Davis has a CUME_DIST of 0.200, indicating that 20% of the dashers have a pay per hour less than or equal to his. Mary Mills has a CUME_DIST of 0.400, placing her below the 50th percentile.
The CUME_DIST function allows you to understand the cumulative position of each value within a group, which is particularly useful for comparative analysis and performance evaluation.
- NTILE
The NTILE function distributes the rows in an ordered partition into a specified number of approximately equal groups. This can be useful for tasks like dividing employees into performance quartiles or any other form of grouped ranking.
NTILE is calculated as follows:
NTILE(n)
Where n is the number of groups into which you want to divide your data.
For example, we want to target DoorDash dashers by dividing them into two groups based on their total pay per hour in the last 30 days. The following query identifies these dashers, their email addresses, and their group.
3.1 SQL Query:
| WITH total_pay AS ( SELECT dasher_id, SUM(pay_received) / SUM(hours_worked) AS pay_per_hour FROM timesheet_by_day WHERE date >= current_date – 30 GROUP BY dasher_id ) SELECT d.first_name, d.last_name, d.email, NTILE(2) OVER (ORDER BY tp.pay_per_hour) AS pay_group FROM total_pay tp JOIN dashers d ON tp.dasher_id = d.id ORDER BY pay_group, tp.pay_per_hour; |
3.2 Explanation:
- The CTE total_pay calculates the pay per hour for each dasher in the last 30 days.
- NTILE(2) OVER (ORDER BY tp.pay_per_hour) divides the dashers into two groups based on their pay per hour.
3.3 Output:
+-----------+----------+--------------------+-----------+
|first_name |last_name |email               | pay_group |
+-----------+----------+--------------------+-----------+
|David      |Davis     |david.davis@dash.com| 1         |
|Mary       |Mills     |mary.mills@dash.com | 1         |
|Fred       |French    |fred.french@dash.com| 1         |
|Greg       |German    |greg.german@dash.com| 2         |
|Simon      |Smith     |simon.smith@dash.com| 2         |
+-----------+----------+--------------------+-----------+
This output shows the group each dasher belongs to based on their pay per hour. For example, David Davis, Mary Mills, and Fred French are in group 1, indicating they fall in the lower half of the pay distribution, while Greg German and Simon Smith are in group 2, indicating they fall in the upper half.
Using the NTILE function, you can easily divide your dataset into a specified number of groups. This is particularly useful for performance analysis and creating ranked segments within your data.
- NTH_VALUE
The NTH_VALUE function returns the value of the nth row in the ordered set of values. This function is useful for retrieving specific values from the dataset, such as the nth highest or lowest value within a group.
NTH_VALUE is calculated as follows:
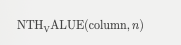
Where column is the column from which to retrieve the value and n is the position of the row to retrieve within the partition.
For example, we want to target DoorDash dashers by retrieving the second-highest pay per hour in the last 30 days. The following query identifies these dashers, their email addresses, and their second-highest pay per hour.
4.1 SQL Query:
| WITH total_pay AS ( SELECT dasher_id, SUM(pay_received) / SUM(hours_worked) AS pay_per_hour FROM timesheet_by_day WHERE date >= current_date – 30 GROUP BY dasher_id ) SELECT d.first_name, d.last_name, d.email, NTH_VALUE(tp.pay_per_hour, 2) OVER (ORDER BY tp.pay_per_hour DESC) AS second_highest_pay FROM total_pay tp JOIN dashers d ON tp.dasher_id = d.id ORDER BY tp.pay_per_hour DESC; |
4.2 Explanation:
- The CTE total_pay calculates the pay per hour for each dasher in the last 30 days.
- NTH_VALUE(tp.pay_per_hour, 2) OVER (ORDER BY tp.pay_per_hour DESC) retrieves the second highest pay-per-hour value for each dasher.
4.2 Output:
+-----------+----------+--------------------+--------------------+
|first_name |last_name |email               | second_highest_pay |
+-----------+----------+--------------------+--------------------+
|Simon      |Smith     |simon.smith@dash.com| 16.00              |
|Greg       |German    |greg.german@dash.com| 16.00              |
|Fred       |French    |fred.french@dash.com| 16.00              |
|Mary       |Mills     |mary.mills@dash.com | 16.00              |
|David      |Davis     |david.davis@dash.com| 16.00              |
+-----------+----------+--------------------+--------------------+
This output shows the second-highest pay per hour for each dasher. For example, the second-highest pay per hour for all listed dashers is 16.00.
By using the NTH_VALUE function, you can retrieve specific values from your dataset, which is particularly useful for detailed analysis and reporting on particular data points within a group.
Pros and Cons of SQL Window Functions
SQL window functions offer a range of powerful features that can significantly improve your data analysis capabilities. However, like any tool, they come with their own set of advantages and disadvantages.
Let’s examine the pros and cons of SQL window functions to better understand their impact on SQL queries and overarching database performance.
Pros of SQL Window Functions
Understanding the benefits of SQL window functions can help you leverage their full potential in your data analysis tasks. Here are some of the key advantages that make window functions a valuable addition to your SQL toolkit.
- Enhanced Analytical Capabilities
SQL window functions significantly improve your analytical capabilities by allowing you to easily perform complex calculations such as running totals, moving averages, and cumulative sums.
For example, when analyzing time series data, windows functions simplify the process by enabling calculations across a specified set of rows related to the current row. This ability to handle sophisticated analyses directly within your SQL queries makes window functions indispensable for data analysts and engineers.
By leveraging SQL aggregate functions in conjunction with window functions, you can derive deeper insights from your datasets, making tasks like computing cumulative sums in SQL much more straightforward.
- Flexibility
One of the standout advantages of SQL window functions is the flexibility. Unlike traditional aggregate functions that collapse rows into a single result, window functions can apply calculations to a subset of rows while retaining the original row structure. This means you can perform calculations without losing any detail in your dataset.
For instance, window functions are particularly useful when you compute cumulative sales per customer without aggregating all rows into a single output. This flexibility extends to using a SQL partition by clause, allowing for precise control over how data is grouped and calculated.
- Efficiency
Window functions can improve the efficiency of your SQL queries by reducing the need for multiple joins and subqueries. By allowing you to perform calculations directly within the query, window functions simplify the query structure and can enhance performance.
For example, a complex query involving multiple subqueries to calculate running totals or ranks can be streamlined using window functions, resulting in faster and more efficient query execution.
This efficiency is especially noticeable when dealing with SQL running total calculations, where window functions can significantly reduce query complexity.
- Readability
SQL window functions also improve the readability and maintainability of your queries. By allowing complex calculations to be performed within the same query, they eliminate the need for nested subqueries and multiple joins, making your SQL code cleaner and easier to understand.
For example, using window functions to calculate rankings or moving averages within a single query block can make your SQL scripts more intuitive and easier to maintain. The SQL frame clause in window functions also helps define precise data ranges for calculations, enhancing the clarity of your code.
Cons of SQL Window Functions
Despite their numerous advantages, SQL window functions come with several drawbacks that must be considered.
- Performance Overhead
While SQL window functions offer powerful capabilities, they can introduce performance overhead, mainly when working with large datasets. The calculations performed by window functions can be resource-intensive, potentially slowing down query execution.
For instance, in scenarios where you are working with millions of rows, using window functions might lead to slower performance than using more straightforward query structures.
- Complexity
Window functions can be complex to understand and use correctly. They require a deep understanding of SQL and the specific syntax and behavior of window functions. This complexity can lead to mistakes and inefficiencies if not used properly.
For instance, misusing partitioning and ordering clauses in window functions can result in incorrect calculations and unexpected results. Familiarizing yourself with SQL advanced queries and practicing different scenarios can mitigate this complexity.
- Database Support
Not all databases support all types of window functions, which can result in compatibility issues. While most modern SQL databases, such as PostgreSQL, SQL Server, and Oracle, offer comprehensive support for window functions, others may have limited functionality.
For example, older versions of MySQL lack support for some window functions, which could be a limitation if you work with a mixed database environment. Checking for specific SQL windowing functions supported by your database can help avoid compatibility issues.
- Resource Intensive
Windows functions can be resource intensive, potentially affecting the overall performance of your database system. They require significant memory and processing power, especially when used extensively in complex queries.
For instance, performing multiple window function calculations on large datasets can lead to high CPU and memory usage, impacting the performance of other database operations. Understanding the impact of SQL data analysis functions on system resources is vital for efficient database management.
Additional Resources
To further enhance your understanding of SQL window functions and related SQL topics, here are some valuable resources from Big Tech Interviews:
- CTE in SQL: Learn about Common Table Expressions (CTEs) in SQL and how they can simplify complex queries in this Comprehensive Guide to Mastering SQL Common Table Expressions. This all-encompassing guide includes an overview as well as many practical examples that will help you understand their power.
- Amazon Data Analyst Interview Guide: Prepare for data analyst interviews at Amazon with this detailed guide to interviewing for a data analyst position at Amazon. It includes a variety of SQL interview questions, practical examples, and detailed solutions to help you succeed in your interview.
- Amazon SQL Interview Questions: Explore a collection of SQL questions commonly asked at Amazon. This resource offers practical examples and detailed explanations to enhance your interview preparation.
- Meta Data Engineer Interview: This guide provides insights into Meta’s data engineer interview process. It covers SQL-related questions and scenarios, providing valuable information for anyone preparing for a technical interview.
- Top 11 Leetcode Alternatives for Data Analysts and Data Scientists: Discover alternative platforms to Leetcode for practicing data analyst and data scientist interview questions. This article reviews various platforms and their features to help you find the best resources for your preparation.
- Meta Data Engineer Interview: A Complete Guide: An in-depth guide to preparing for data engineer interviews at Meta. This comprehensive resource covers all aspects of the interview process, including SQL-related questions and practical tips.
- SQL Joins: A Complete Guide: Master SQL joins with this detailed guide, covering all types of joins and their use cases. Understanding joins is crucial for working with complex queries and data transformations.
- 3 Latest Google SQL Interview Questions: Review recent SQL interview questions asked at Google to help you prepare for your interview. This resource provides insights into the types of SQL questions Google asks and offers practical solutions to these questions.
- SQL CASE WHEN: Understand how to use the CASE WHEN statement in SQL to create conditional queries. This article includes practical examples and best practices to help you implement conditional logic in your SQL queries effectively.
- SQL UNION vs UNION ALL: Learn the difference between UNION and UNION ALL in SQL and when to use each. This resource explains the concepts with practical examples to improve your understanding and application of these SQL operations.
In Conclusion
Mastering SQL window functions is essential for anyone working with relational databases, especially data analysts, data scientists, SQL developers, and data engineers. These powerful functions allow you to perform calculations across a set of table rows that are related to the current row without collapsing the result set. This capability is invaluable for complex data analysis and reporting tasks.
This comprehensive guide has explored various types of SQL window functions, including their syntax, use cases, and practical examples. From performing running totals and moving averages to ranking and partitioning data, you now understand how to leverage these functions to streamline your data retrieval and analysis.
By applying SQL window functions in your queries, you can enhance your analytical capabilities, improve query performance, and simplify complex calculations. These tools are indispensable for performing detailed and sophisticated data analysis, making you more proficient in handling complex data tasks.
Whether you’re preparing for an SQL interview, looking to improve your professional skills, or optimizing your database management capabilities, the knowledge you’ve gained here will be invaluable.
By exploring the additional resources provided, you can further solidify your understanding of SQL window functions, improve your query writing skills, and prepare effectively for technical interviews.
The insights and examples provided will help you master SQL, from SQL ranking functions and analytical functions to advanced queries and the use of the SQL partition by clause. This will allow you to apply these skills confidently in interviews and real-world scenarios.
Take the next step in mastering SQL window functions and other advanced SQL topics by visiting Big Tech Interviews. You’ll find a wealth of resources there, including practical examples, comprehensive guides, and interview preparation materials.
Whether you’re a seasoned professional or just starting out, these resources will help you refine your SQL skills and achieve your career goals. Start exploring today and become proficient in SQL data analysis functions, the SQL frame clause, SQL running total calculations, and much more.
Enhance your expertise and take your SQL skills to the next level with bigtechinterviews.com.
Frequently Asked Questions (FAQs)
SQL window functions can sometimes be challenging to grasp fully. To help clarify their usage and benefits, we’ve compiled answers to some of the most frequently asked questions about SQL window functions.
- What are window functions in SQL?
Window functions in SQL are powerful tools that allow you to perform calculations across a set of table rows related to the current row. Unlike aggregate functions, which return a single value for each group of rows, window functions return a value for each row in the result set. They are defined using the OVER clause, which specifies the window or set of rows the function will operate on.
- How to use window functions in SQL?
To use window functions in SQL, you typically include the function in your SELECT statement and define the window using the OVER clause. The OVER clause can consist of components such as PARTITION BY (to divide the result set into partitions), ORDER BY (to order the rows within each partition), and a frame specification (ROWS or RANGE).
Here’s an example:
| SELECT employee_id, salary, AVG(salary) OVER (PARTITION BY department_id ORDER BY hire_date ROWS BETWEEN 1 PRECEDING AND 1 FOLLOWING) AS avg_salary FROM employees; |
- Are SQL window functions efficient?
SQL window functions are generally efficient and can improve the performance of your queries by reducing the need for multiple joins and subqueries. However, due to their resource-intensive nature, they can introduce performance overhead when working with large datasets. Optimizing the use of window functions by understanding their behavior and impact on your database can help mitigate potential performance issues.
- What does the OVER() clause do in SQL window functions?
The OVER() clause in SQL window functions defines the set of rows that the window function will operate on. It allows you to specify partitions and ordering for your calculations. The OVER() clause can include:
- PARTITION BY to divide the result set into partitions.
- ORDER BY to specify the sequence of rows within each partition.
- ROWS or RANGE to define a frame of rows relative to the current row for the calculation.
For example, the following query uses the OVER() clause to calculate a running total of sales ordered by the sales date within each employee partition:
| SELECT employee_id, sales_date, total_sales, SUM(total_sales) OVER (PARTITION BY employee_id ORDER BY sales_date) AS running_total FROM sales_data; |
- When should I use an SQL window function?
You should use SQL window functions when you need to perform calculations across a set of table rows related to the current row without collapsing the result set. They are particularly useful for running totals, moving averages, rankings, and other analytical calculations. For instance, if you need to rank employees by sales within each department or calculate a moving average of sales over time, window functions are ideal.