


Introduction
Data Engineers play a critical role in today’s data-driven organizations. They are responsible for building and maintaining the pipelines and infrastructure that power analytics, working closely with Data Science, Engineering, and Product teams. As the demand for skilled Data Engineers continues to grow, the interview process has become more competitive and complex. This guide walks you through the SQL interview process for Data Engineers, providing key questions and answers to help you prepare. Whether you’re an experienced professional refining your skills or someone new to the field, you’ll find practical insights to help you succeed in your next SQL interview.

Data Engineer SQL Interview Questions
There’s no shortcut to success. If you want to ace your interview, you’ve got to put in the time to vigorously prepare.
- Apple SQL Question: Calculate the overall sales rankings for all employees combined over the observed period.
- Uber SQL Question: Find the latest timestamp for users who took at least one trip
- Robinhood SQL Question: Customers with a 10-second gap between each other
- Tesla SQL Question: Find the total revenue rounded to the second decimal place
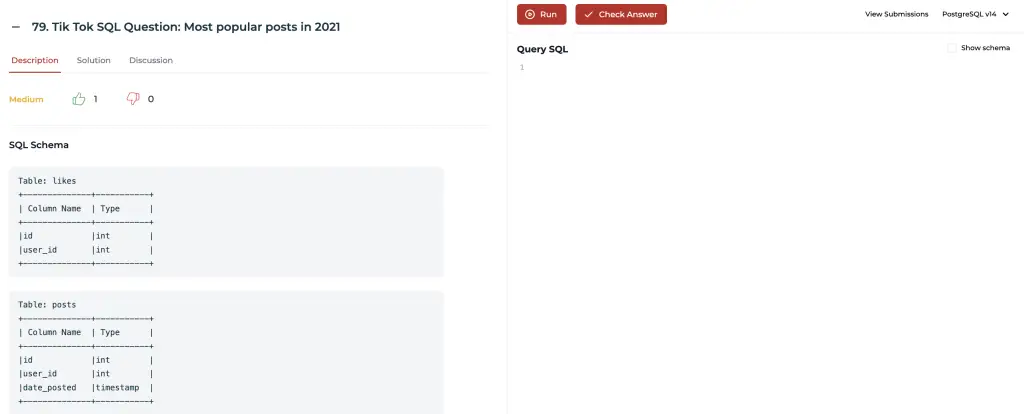
- Tik Tok SQL Question: Most popular posts in 2021
Question 1: Calculate the overall sales rankings for all employees combined over the observed period.
This candidate was asked in a recent interview to calculate the the overall sales rankings for all employees combined over the observed period using the sales_data table.
Table: sales_data
+------------+-----------+------------+
|employee_id | sales_date| total_sales|
+------------+-----------+------------+
|101         |2024-01-01 |500         |
|102         |2024-01-01 |700         |
|103         |2024-01-01 |600         |
|101         |2024-01-02 |800         |
|102         |2024-01-02 |750         |
|103         |2024-01-02 |900         |
|101         |2024-01-03 |600         |
|102         |2024-01-03 |850         |
|103         |2024-01-03 |700         |
+------------+-----------+------------+
Output
+------------+------------+------------+
| employee_id| total_sales| sales_rank |
+------------+------------+------------+
| 102        | 2300       | 1          |
| 103        | 2200       | 2          |
| 101        | 1900       | 3          |
+------------+------------+------------+
Before checking the solution, you can try to solve this real Data Engineer SQL interview question online in our interactive SQL code editor:

SQL Solution
					SELECT
  employee_id,
  SUM(total_sales) AS total_sales_sum,
  RANK() OVER (
    ORDER BY
      SUM(total_sales) DESC
  ) AS sales_rank
FROM
  sales_data
GROUP BY
  employee_id;
Table: sign_ups
+--------+----------------+
|rider_id|signup_timestamp|
+--------+----------------+
|1       |2022-03-01      |
|2       |2022-03-01      |
|3       |2022-03-01      |
|4       |2022-03-01      |
|5       |2022-03-01      |
+--------+----------------+
Table: trips
+-------+--------+---------+--------------+
|trip_id|rider_id|driver_id|trip_timestamp|
+-------+--------+---------+--------------+
|1      |1       |2        |2022-02-01    |
|1      |2       |2        |2022-03-11    |
|1      |1       |2        |2022-04-01    |
|1      |1       |2        |2022-05-21    |
|1      |2       |2        |2022-06-01    |
|1      |3       |2        |2022-07-31    |
+-------+--------+---------+--------------++---------+------------------------+
|rider_id |latest_trip_timestamp |
+---------+------------------------+
|1 |2022-05-21T00:00:00.000Z|
|2 |2022-06-01T00:00:00.000Z|
|3 |2022-07-31T00:00:00.000Z|
+---------+------------------------+Try your hand at solving this actual Data Engineer SQL interview question in our online, interactive SQL code editor prior to exploring the solution.

SQL Solution
					select
rider_id
,max(trip_timestamp) latest_trip_timestamp
from trips
group by rider_id
having count(trip_id)>=1
order by rider_id asc
Table: customer_transactions
+---+-------------+-------------------+------------------+
|id |customer_name|transaction_time   |transaction_amount|
+---+-------------+-------------------+------------------+
|1  |A            |2022-02-21 15:21:10|533               |
|2  |B            |2022-02-21 15:21:20|234               |
|3  |D            |2022-02-21 15:21:25|789               |
|4  |D            |2022-02-21 15:21:45|34                |
|5  |F            |2022-02-21 15:21:40|12                |
|6  |A            |2022-02-21 15:22:05|445               |
|7  |B            |2022-02-21 15:22:15|236               |
|8  |C            |2022-02-21 15:22:30|643               |
|9  |F            |2022-02-21 15:22:40|563               |
|10 |C            |2022-02-21 15:22:60|876               |
+---+-------------+-------------------+------------------++--------------+
|customer_name |
+--------------+
|A |
|B |
|C |
|F |
+--------------+Before peeking at the solution, consider tackling this real Data Engineer SQL interview question yourself using our dynamic SQL code editor online.

SQL Solution
					with measured as (
select
customer_name
,date_part('seconds'
,transaction_time
-
lag(transaction_time) over (
partition by customer_name
order by transaction_time asc
)
) seconds_between
from customer_transactions
)
select customer_name
from measured
where seconds_between<=10
order by customer_name asc;
Table: Customers
+----+--------------+--------------------------+
| Id | Name         | Email                    |
+----+--------------+--------------------------+
| 1  | John Smith   | john.smith@example.com   |
| 2  | Mary Johnson | mary.johnson@example.com |
| 3  | David Lee    | david.lee@example.com    |
+----+--------------+--------------------------+
Table: Orders
+----+------------+------------+--------+
| Id | CustomerId | OrderDate  | Total  |
+----+------------+------------+--------+
| 1  | 1          | 2022-01-01 | 100.00 |
| 2  | 1          | 2022-02-01 | 50.00  |
| 3  | 2          | 2022-01-15 | 200.00 |
| 4  | 2          | 2022-02-15 | 150.00 |
| 5  | 3          | 2022-01-31 | 75.00  |
| 6  | 3          | 2022-02-28 | 125.00 |
+----+------------+------------+--------++-------------+--------------+
|name | totalrevenue |
+-------------+--------------+
|Mary Johnson | 350.00 |
|David Lee | 200.00 |
|John Smith | 150.00 |
+-------------+--------------+Before unveiling the answer, we encourage you to take on this genuine Data Engineer SQL challenge on your own with our dynamic SQL code editor online

SQL Solution
					SELECT
    Customers.Name,
    ROUND(SUM(Orders.Total),2) AS TotalRevenue
FROM
    Customers
    INNER JOIN Orders ON Customers.Id = Orders.CustomerId
GROUP BY
    Customers.Name
ORDER BY
    TotalRevenue DESC;
Table: likes
+----+--------+
|id  |user_id |
+----+--------+
|1   |12340   |
|5   |12341   |
|2   |12342   |
|3   |12343   |
|3   |12344   |
|4   |12345   |
|1   |12346   |
+----+--------+
Table: posts
+----+--------+-------------------+
|id  |user_id |date_posted        |
+----+--------+-------------------+
|1   |12342   |2021-01-02 08:00:00|
|2   |12342   |2021-02-06 07:30:00|
|3   |12341   |2021-05-23 22:15:00|
|4   |12343   |2021-04-12 21:30:00|
|5   |12344   |2021-07-30 10:25:00|
+----+--------+-------------------++----+----------+
|id |num_likes |
+----+----------+
|5 |1 |
|4 |1 |
|2 |1 |
+----+----------+Think you can answer this one without checking the solution? Practice this real Data Engineer SQL question on your own with our dynamic SQL code editor online.
SQL Solution
					with ranked as (
select
p.id
,count(l.user_id) num_likes
,rank() over (
order by count(l.user_id) desc
) num_likes_rank
from posts p
left join likes l
on l.id=p.id
where date_part('year',p.date_posted)=2021
group by p.id
)
select id, num_likes
from ranked
where num_likes_rank=3;
Data Engineer SQL Interview Concepts
Join Types Explained with Examples:
In SQL, understanding different join types is essential for effectively merging data across various tables. Here are detailed explanations and examples of join types vital for Data Engineers:
- INNER JOIN: This join retrieves rows where there is at least one match in both tables involved. It’s the most common type of join.
- LEFT OUTER JOIN (or LEFT JOIN): This returns all rows from the left table, along with the matching rows from the right table. If there’s no match, the right side will contain null.
- RIGHT OUTER JOIN (or RIGHT JOIN): Opposite to the LEFT JOIN, this returns all rows from the right table, along with the matching rows from the left table. If there’s no match on the left, you’ll see null on the left side.
- FULL OUTER JOIN (or FULL JOIN): This join returns rows when there is a match in either of the tables. It essentially combines the results of both LEFT JOIN and RIGHT JOIN.

To elucidate the differences among these joins, imagine we’re analyzing the correlation between sales metrics and their related sales associates across different territories. For this analysis, consider two primary tables: sales_records and agents . These tables are interconnected via the agent_id field, which acts as a foreign key in the sales_records table and a primary key in the agents table.
Here’s a simplified schema of what the setup looks like: DB-Fiddle
					CREATE TABLE sales_records (
   record_id INT PRIMARY KEY,
   agent_id INT,
   territory VARCHAR(50),
   amount_sold DECIMAL(10, 2)
);
CREATE TABLE agents (
   agent_id INT PRIMARY KEY,
   name VARCHAR(100),
   territory VARCHAR(50)
);

INSERT INTO sales_records (record_id, agent_id, territory, amount_sold) VALUES
(1, 201, 'North', 1000.00),
(2, 202, 'South', 1500.50),
(3, 203, 'East', 2000.00),
(4, null, 'West', 2500.75);
INSERT INTO agents (agent_id, name, territory) VALUES
(201, 'Alice Adams', 'North'),
(202, 'Bob Brown', 'South'),
(205, 'Charlie Chaplin', 'West'),
(206, 'Diana Dove', 'East');
For instance, to pair sales with agents in the North territory using an INNER JOIN, we fetch rows with matching agent_id in both tables:
					SELECT sr.amount_sold, a.name
FROM sales_records sr
INNER JOIN agents a ON sr.agent_id = a.agent_id
WHERE sr.territory = 'North';
If we’re interested in observing all sales in the East territory, inclusive of those without a paired agent, a LEFT JOIN proves useful:
					SELECT sr.amount_sold, a.name
FROM sales_records sr
LEFT JOIN agents a ON sr.agent_id = a.agent_id
WHERE sr.territory = 'East';
Conversely, to view all agents within the West territory, regardless of their sales records, we’d opt for a RIGHT JOIN:
					SELECT sr.amount_sold, a.name
FROM sales_records sr
RIGHT JOIN agents a ON sr.agent_id = a.agent_id
WHERE a.territory = 'West';
Finally, to explore all possible connections between sales and agents across every territory, employing a FULL JOIN achieves this:
					SELECT sr.amount_sold, a.name
FROM sales_records sr
FULL JOIN agents a ON sr.agent_id = a.agent_id;
By mastering these joins, Data Engineers can adeptly handle complex data relationships, enhancing their capability to draw insightful data-driven conclusions.
Subqueries Explained with Examples:
Subqueries, sometimes known as inner queries, are powerful tools that allow the execution of one query nestled within another SQL statement. On the other hand, Common Table Expressions (CTEs) create a temporary set of results that can be easily referred to within the main SQL query. This duo of techniques is pivotal for crafting more dynamic and complex data retrieval commands.
Subqueries:
- Scalar Subquery: This is a subquery designed to return a singular value.
- Column Subquery: A subquery that yields one or multiple columns.
- Table Subquery: This acts as a temporary table for use in the main query.
CTEs:
- Serve as an organized, maintainable alternative to complex subqueries.
- Capable of self-referencing, which proves highly beneficial for recursive operations.
For an applied understanding, let’s examine examples centered around a telecommunication database setup: Visit this DB-Fiddle link.
We’re working with two tables:
					CREATE TABLE all_numbers (
 "phone_number" VARCHAR(25)
);
CREATE TABLE confirmed_numbers (
 "phone_number" VARCHAR(25)
);

INSERT INTO all_numbers ("phone_number") VALUES
('706-766-8523'), ('555-239-6874'), ('407-234-5041'), ('(123)351-6123'), ('251-874-3478');
INSERT INTO confirmed_numbers
("phone_number")
VALUES ('555-239-6874'), ('407-234-5041'), ('(123)351-6123');
Imagine you are tasked with identifying unconfirmed phone numbers—that is, numbers in all_numbers not found in confirmed_numbers. You can approach this using both methodologies:
Using a traditional subquery:
					SELECT phone_number
FROM all_numbers
WHERE phone_number NOT IN (
 SELECT phone_number
 FROM confirmed_numbers);
Leveraging a CTE for improved performance in sizable datasets:
					WITH excluded_numbers AS (
 SELECT phone_number
 FROM confirmed_numbers
)
SELECT phone_number
FROM all_numbers
WHERE phone_number NOT IN (
 SELECT phone_number
 FROM excluded_numbers);
By contrasting subqueries with CTEs, we showcase their unique strengths—subqueries for concise operations and CTEs for enhanced readability and recursive data handling. Utilizing these tools astutely allows data engineers to tackle intricate data manipulation tasks efficiently.
Data Modeling Explained with Examples
Data modeling is an essential process in structuring and defining how data is stored, processed, and accessed within a system. It acts as a blueprint for creating databases that support business requirements effectively. There are several types of data models, each serving different purposes, from conceptual models that provide a high-level understanding of the data to physical models that detail exactly how data is stored in databases.
Types of Data Models:
- Conceptual Data Models: These models provide an overall view of the business concepts and relationships between them. They are technology-agnostic and serve as the foundation for more detailed data modeling.
- Logical Data Models: Building on the conceptual model, logical models include more details like specific fields, data types, and relationships. They refine the model without getting into the specifics of how the model will be implemented.
- Physical Data Models: The most detailed, these models translate the logical model into an actual database structure. They specify tables, columns, data types, indexes, and how entities are related, catering to a specific type of database management system (DBMS).
For practical application, consider a scenario involving an e-commerce platform. This platform requires a database to manage users, products, and orders. The design process would start with a data model.
Conceptual Model Example:
At the conceptual level, you’d identify the core entities: Users, Products, and Orders. Each user can have multiple orders, and each order can include multiple products. This stage is about understanding relationships without worrying about data fields or database specifics.
Logical Model Example:
Transitioning to a logical model, you define properties for each entity:
- Users: UserID (Primary Key), Name, Email
- Products: ProductID (Primary Key), Name, Price
- Orders: OrderID (Primary Key), UserID (Foreign Key), OrderDate
- OrderDetails: OrderID (Foreign Key), ProductID (Foreign Key), Quantity
This stage details the structure and relationships, like how an Order is linked to the User who made it and to the Products it contains.
Physical Model Example:
Lastly, for the physical model, you translate the logical model into SQL statements tailored for a specific DBMS, such as MySQL:
					CREATE TABLE Users (
 UserID INT PRIMARY KEY AUTO_INCREMENT,
 Name VARCHAR(100),
 Email VARCHAR(100)
);
CREATE TABLE Products (
 ProductID INT PRIMARY KEY AUTO_INCREMENT,
 Name VARCHAR(100),
 Price DECIMAL(10, 2)
);
CREATE TABLE Orders (
 OrderID INT PRIMARY KEY AUTO_INCREMENT,
 UserID INT,
 OrderDate DATE,
 FOREIGN KEY (UserID) REFERENCES Users(UserID)
);
CREATE TABLE OrderDetails (
 OrderID INT,
 ProductID INT,
 Quantity INT,
 FOREIGN KEY (OrderID) REFERENCES Orders(OrderID),
 FOREIGN KEY (ProductID) REFERENCES Products(ProductID)
);
This example illustrates how the database structure is designed to efficiently store and organize e-commerce data, from a high-level understanding down to specific implementation details. Through conceptual, logical, and physical models, data modeling enables the structured and efficient design of databases tailored to specific business needs.
Conclusion
Data manipulation and modeling are crucial components in the world of data analytics. They allow for efficient handling and organization of large amounts of data, enabling businesses to gain valuable insights and make informed decisions. By utilizing tools like subqueries and CTEs, data engineers can efficiently manipulate complex datasets, while data modeling allows for a structured approach to database design that supports business requirements effectively. These techniques, when used skillfully, can provide businesses with a competitive advantage in today’s data-driven world. So, it is important for data engineers to constantly enhance their skills and stay up-to-date with emerging technologies and best practices in these areas. Keep learning and unlocking the potential of your data!